Elastic
Jina AI
Models
API
keyboard_arrow_down
Reader
Convert any URL to Markdown for better grounding LLMs.
Embeddings
Multimodal multilingual embeddings.
Reranker
Reranker for maximizing search relevance.
MCP
terminal
CLI
article
llms.txt
smart_toy
Agents
data_object
Schema
menu_book
Docs
Log in
login
Embeddings
copyright CC BY-NC 4.0
open_in_new Release Post

jina-code-embeddings-0.5b

Efficient code embeddings from code generation models
License
copyright CC-BY-NC-4.0
Release Date
calendar_month
2025-09-01
Input
abc
Text (Code)
arrow_forward
Output
more_horiz
Vector
Matryoshka Dimensions help_outline
64
128
256
512
896
Model Details
Parameters: 494M
Input Token Length: 32K
Output Dimension: 896
Base Model help_outline
open_in_new
Qwen2.5-Coder-0.5B
Trained Languages help_outline
1 languages
Supported Languages help_outline
29 languages
Quantizations help_outline
GGUF
Related Models
link
jina-code-embeddings-1.5b
link
jina-embeddings-v2-base-code
Supported Tasks
translate NL→Code
help_center Tech QA
sync_alt Code→Code
description Code→NL
auto_fix_high Completion
Available via
Jina API
AWS SageMaker
Microsoft Azure
Google Cloud
Hugging Face
Air-gapped
I/O graph

Code

jina-code-embeddings

Task

Vector

Pareto fronthelp_outline
CoIR
MTEB Code
chevron_leftchevron_right
30M100M300M1B3.0B10B40506070bge-base-en-v1.5bge-m3bge-small-en-v1.5CodeRankEmbedCodeSage-baseCodeSage-largeCodeSage-large-v2CodeSage-smallCodeXEmbed-7BContrievere5-base-v2e5-mistral-7b-instructe5-small-v2granite-embedding-engli…granite-embedding-small…gte-base-en-v1.5gte-modernbert-basegte-Qwen2-1.5B-instructjina-embeddings-v3jina-embeddings-v4modernbert-embed-baseNV-Embed-v2SFR-Embedding-2_RSFR-Embedding-Code-2B_RSFR-Embedding-Code-400M…snowflake-arctic-embed-…UniXcoderjina-code-embeddings-0.…Parameters (log)nDCG@10
This model
On the front
Jina AI
Other
CoIR
73.94
Parameters
494M
Rank by score
1 / 31
Pareto front
On it
Value distributionhelp_outline
AUC 0.8538
Corpus
Translation pairs
Doc retrieval
Code
Task
nl2code.passage
nl2code.query
nl2code.query → nl2code.passage
qa.passage
qa.query
qa.query → qa.passage
0.7330.000.200.400.600.80
Related18.5%
Hard negative2.3%
Unrelated1.1%
Recommended cutoffs
FPR 0.1 · 0.544
FPR 0.01 · 0.733
FPR 0.001 · 0.813
FPR 0.0001 · 0.889
balanced · 0.427
AUC
0.8538
Noise ceiling
0.809
Recall cliff
0.160
Pairs measured
119 / 11k
Vector componentshelp_outline
-0.210.010.23
σ 0.0334 · 213k values
Embedding geometryhelp_outline
0896
Per-dimension mean, hover for a range
Noise floor
0.329
Effective dims
55 / 896
Choose models to compare
Publications (1)
NeurIPS 2025
August 31, 2025
Efficient Code Embeddings from Code Generation Models

Overview

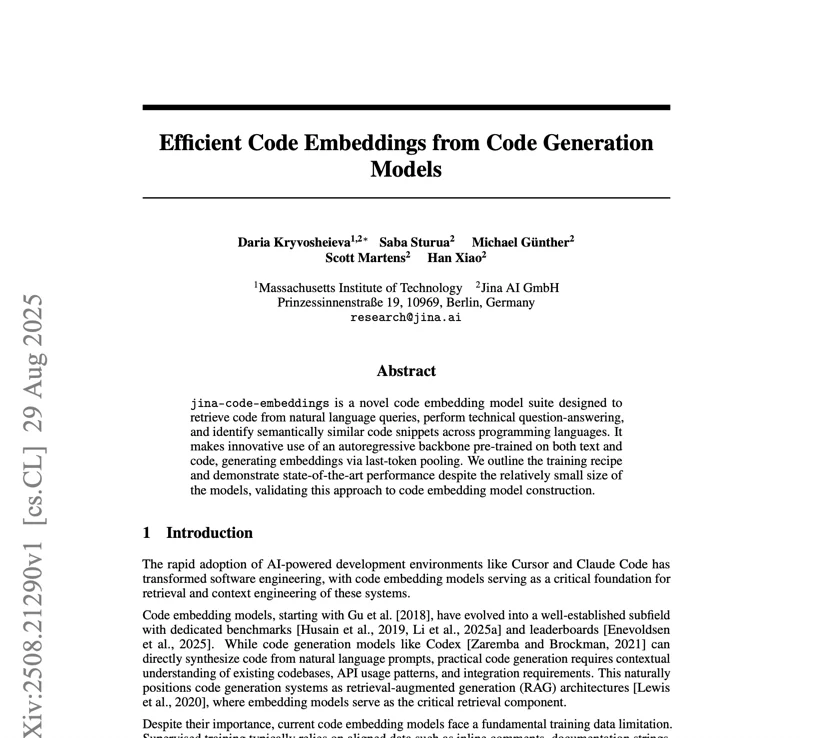
jina-code-embeddings-0.5b is a 494M-parameter code embedding model that maps programming code and natural language queries into a shared 896-dimensional semantic space. It supports 32K token context windows, enabling whole-function and multi-file retrieval, and uses Matryoshka representation learning for flexible dimensionality (64–896). It achieves state-of-the-art code retrieval performance at its size, outperforming models with 3× the parameter count.

Methods

The model is built on an autoregressive transformer backbone pretrained on both natural language and code corpora. Instead of the bidirectional pooling used by traditional embedding models, it extracts embeddings via Last-Token-Pooling from the final position of the sequence. This is a key architectural insight: the autoregressive model's causal attention naturally attends to the full input context, and the code-generation pretraining objective produces rich semantic representations that transfer well to retrieval. Training uses a two-stage recipe: (1) contrastive pretraining on large-scale code-text pairs (natural language descriptions paired with code implementations), (2) supervised fine-tuning on curated code retrieval datasets with hard-negative mining. The 32K context length is enabled through rotary position embeddings with a tuned base frequency.

Performance

The model achieves a 78.41% overall average and 78.72% MTEB Code average across standard code retrieval benchmarks. Notable scores: 96.77% on HumanEval, 89.01% on MBPP, 98.31% on WikiSQL, 99.70% on CodeChefXLang, 90.37% on CodeTransOceanContest (code-to-code), 85.73% on COIR-CodeSearchNet (NL2Code), 95.98% on Doc2Code, and 91.04% on StackOverflowQA. It outperforms Qwen3-Embedding-0.6B and larger models including jina-embeddings-v4 (74.11%) and gemini-embedding-001 (77.38%) on code-specific tasks. At 494M parameters, it outperforms several models 3–5× its size, demonstrating that the autoregressive backbone approach yields high semantic quality per parameter.

Best Practice

Always use appropriate task-specific instruction prefixes: nl2code for natural-language-to-code search, code2code for code-to-code similarity, code2nl for code-to-natural-language, techqa for technical Q&A, and code2completion for code completion. For large codebases, implement chunking at function or class boundaries to stay within the 32K token limit. Matryoshka truncation to 128 or 256 dimensions is suitable for high-throughput indexing; use the full 896 dimensions when re-ranking top candidates. Use cosine similarity for embedding comparison. Optimal batch size is 512, sequence length 512 tokens. The model is optimized for Python, JavaScript, Java, PHP, Go, and Ruby but supports 30+ languages. For RAG pipelines over code, pair with jina-reranker-v3.5 for the second stage to maximize precision on the top-50 candidates.

Blogs that mention this model
October 03, 2025 • 7 minutes read
Jina Reranker v3: 0.6B Listwise Reranker for SOTA Multilingual Retrieval
New 0.6B-parameter listwise reranker that considers the query and all candidate documents in a single context window.
Jina AI
Light blue background with stylized text in the center, composed of small dots or squares, evoking a modern and minimalistic
September 04, 2025 • 6 minutes read
Jina Code Embeddings: SOTA Code Retrieval at 0.5B and 1.5B
Code generation LLMs → code embeddings: 0.5B/1.5B models achieve SOTA performance across 25 code retrieval benchmarks.
Jina AI
Green "Code Embeddings" text displayed in a LED dot style on a black background, evoking a futuristic and technological atmos
Current language / theme
Search Foundation
Reader
Embeddings
Reranker
Get Jina API key
Rate Limit
About us
News
Download Jina logo
open_in_new
Download Elastic logo
open_in_new
API Status
Elastic © 2026.SecurityTerms & ConditionsPrivacyManage CookiesDo Not Sell or Share My Personal Information
This website and all associated content, software, products, and services are intended for professional use only. No consumer use is intended or directed.