

Embeddings
Top-performing multimodal multilingual long-context embeddings for search, RAG and agent applications.
Embedding API
Try our embedding models to improve your search and RAG systems. Start with a free trial!
curl "https://api.jina.ai/v1/embeddings" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $JINA_API_KEY" \
  -d @- <<EOFEOF
{
  "model": null,
  "normalized": true,
  "embedding_type": "float",
  "input": [
    text_fieldsclose"Organic skincare for sensitive skin with aloe vera and chamomile: Imagine the soothing embrace of na…ing, healthy complexion.",
    text_fieldsclose"Bio-Hautpflege für empfindliche Haut mit Aloe Vera und Kamille: Erleben Sie die wohltuende Wirkung u…einen strahlenden Teint.",
    text_fieldsclose"Cuidado de la piel orgánico para piel sensible con aloe vera y manzanilla: Descubre el poder de la n…el radiante y saludable.",
    text_fieldsclose"针对敏感肌专门设计的天然有机护肤产品:体验由芦荟和洋甘菊提取物带来的自然呵护。我们的护肤产品特别为敏感肌设计,温和滋润,保护您的肌肤不受刺激。让您的肌肤告别不适,迎来健康光彩。",
    text_fieldsclose"新しいメイクのトレンドは鮮やかな色と革新的な技術に焦点を当てています: 今シーズンのメイクアップトレンドは、大胆な色彩と革新的な技術に注目しています。ネオンアイライナーからホログラフィックハイライターまで、クリエイティビティを解き放ち、毎回ユニークなルックを演出しましょう。"
    + add input
  ]
}
EOFEOFv5-omni: One Embedding for All
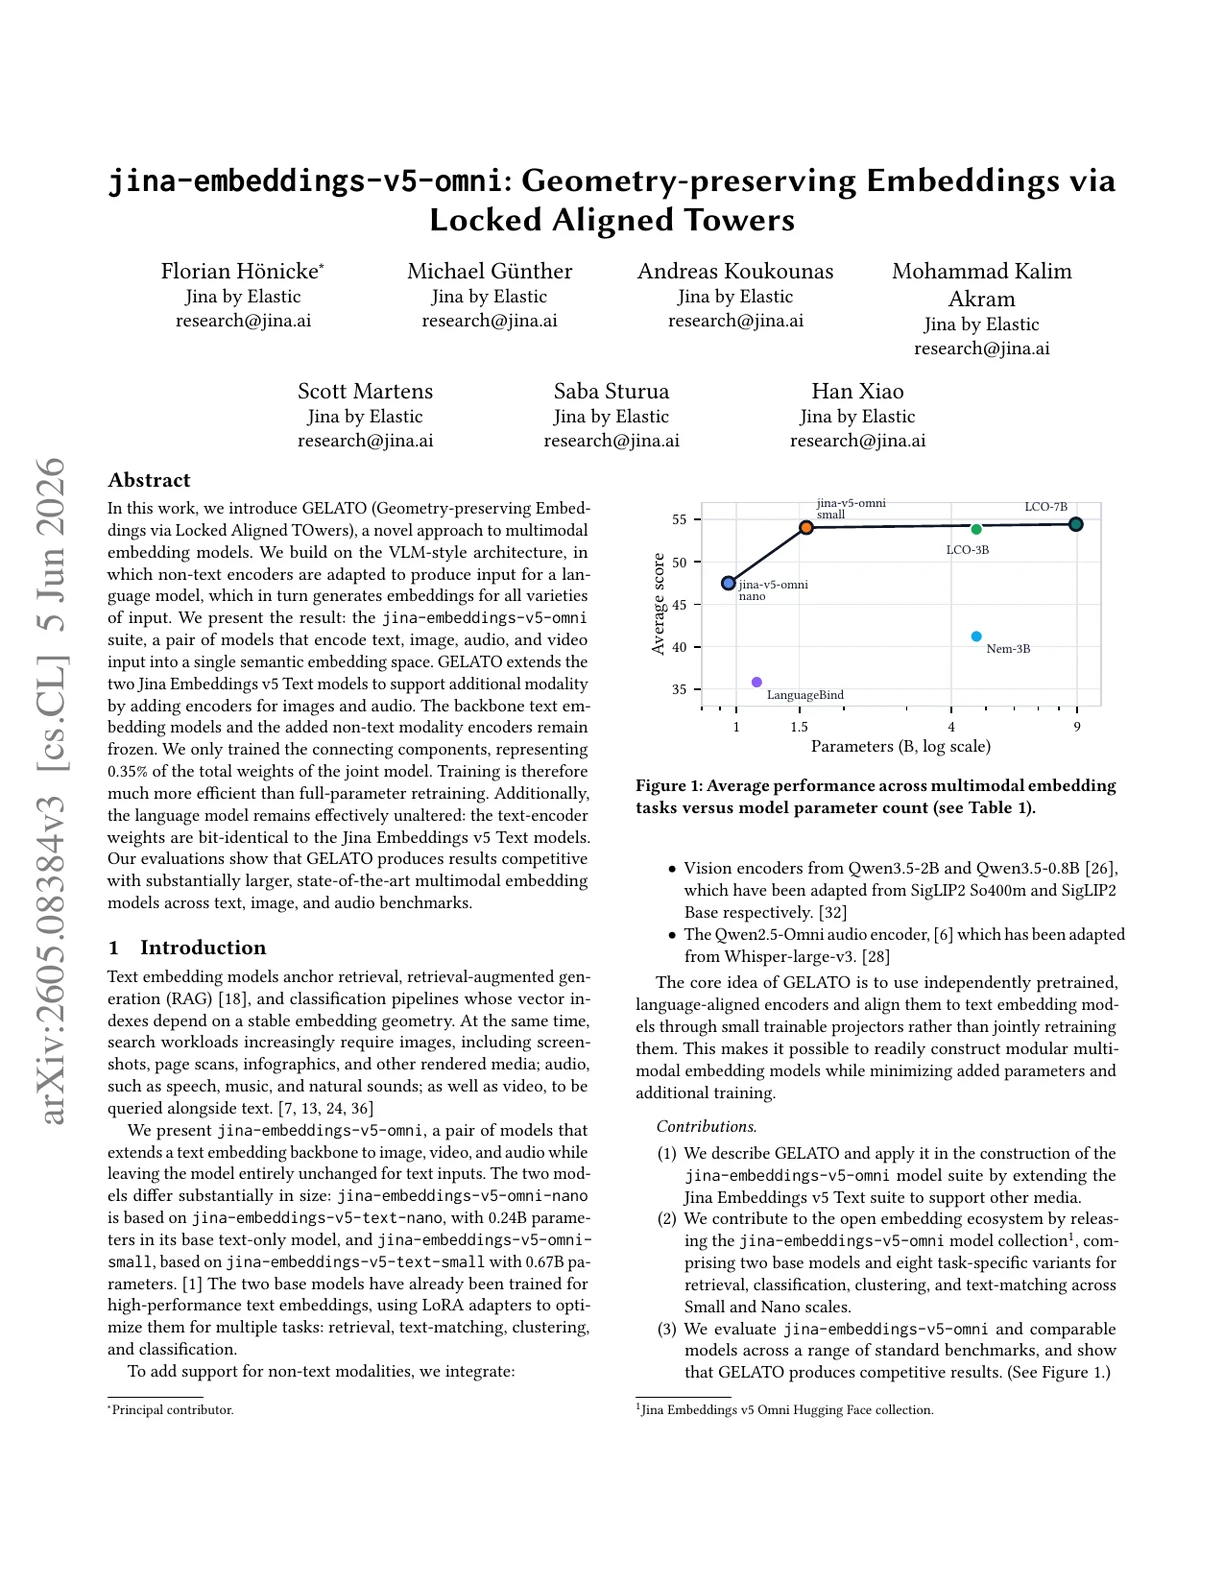
Text, image, audio, video — one shared embedding space, two sizes. v5-omni-small (1.6B) is the best-performing open-weight omni model under 2B parameters. v5-omni-nano (0.9B) delivers competitive retrieval at under 1B. Both are byte-for-byte compatible with v5-text — no reindexing needed.
v5-text: New SOTA Small Multilingual Embeddings
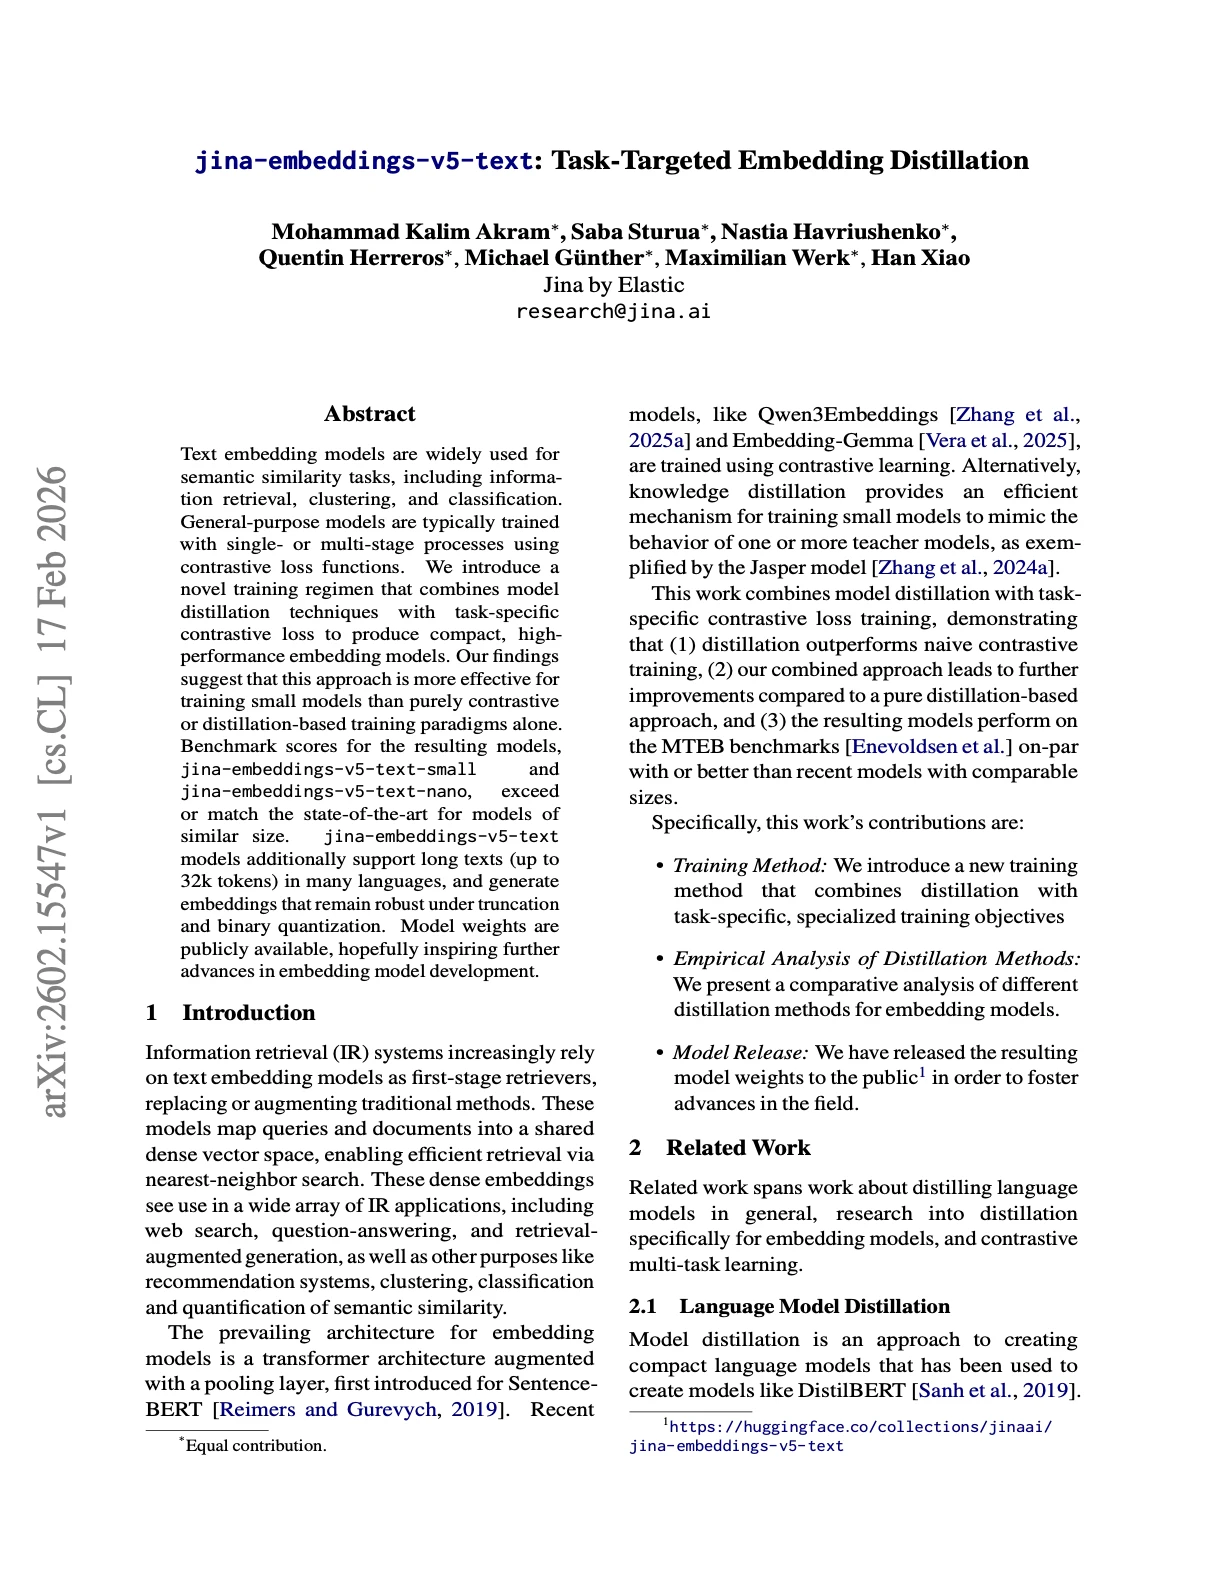
jina-embeddings-v5-text delivers fifth-generation embedding quality in two efficient sizes — a 677M small and 239M nano model — with task-specific LoRA adapters, Matryoshka dimensions, 32K context, and GGUF/MLX quantization for edge deployment, setting new benchmarks across MMTEB, MTEB English, and retrieval tasks.
Two Ways to Purchase
Subscribe to our API or purchase through cloud providers.
radio_button_unchecked
cloud
With 3 cloud service providers
Using AWS or Azure? You can deploy our models directly on your company's cloud platform and handle billing through the CSP account.
radio_button_checked

With Jina Search Foundation API
The easiest way to access all of our products. Top-up tokens as you go.
Top up this API key with more tokens
Please enter the correct API key to top up.
Understand the rate limit
Rate limits are the maximum number of requests that can be made to an API within a minute per IP address/API key (RPM). Find out more about the rate limits for each product and tier below.
keyboard_arrow_down

On-premises deployment
Deploy Jina Embeddings models in AWS SageMaker and Microsoft Azure, and soon in Google Cloud Services, or contact our sales team to get customized Kubernetes deployments for your Virtual Private Cloud and on-premises servers.
 AWS SageMaker
 Embeddings
 Reranker
 Microsoft AzureEmbeddingsReranker
 Google CloudEmbeddings

API Integrations
Our Embedding API is natively integrated with various renowned databases, vector stores, RAG, and LLMOps frameworks. To begin, just copy and paste your API key into any of the listed integrations for a quick and seamless start.
Vector Store
LLMOps
RAG
Observability

MongoDB

DataStax

Qdrant

Pinecone

Chroma

Weaviate
Milvus

Epsilla

MyScale

LlamaIndex

Haystack

Langchain

Dify

SuperDuperDB
%20rotate(-89.93)'/%3e%3crect%20class='cls-1'%20x='30.52'%20y='10.19'%20width='3'%20height='47.42'%20transform='translate(-13.3%2044.91)%20rotate(-60.3)'/%3e%3ccircle%20id='_椭圆形'%20class='cls-1'%20cx='28.91'%20cy='31.28'%20r='5'/%3e%3cpolygon%20class='cls-1'%20points='42.43%2030.75%2035.08%2029.1%2036.37%2021.5%2039.33%2022.01%2038.51%2026.8%2043.09%2027.82%2042.43%2030.75'/%3e%3cpolygon%20class='cls-1'%20points='16.75%2045.55%209.43%2043.77%2010.86%2036.19%2013.8%2036.75%2012.9%2041.53%2017.46%2042.63%2016.75%2045.55'/%3e%3cpolygon%20class='cls-1'%20points='11.02%2028.19%209.54%2020.8%2017.01%2018.89%2017.75%2021.8%2013.04%2023%2013.96%2027.6%2011.02%2028.19'/%3e%3c/g%3e%3c/g%3e%3c/g%3e%3c/svg%3e)
DashVector
Portkey

Baseten

TiDB
LanceDB

Carbon
Our Publications
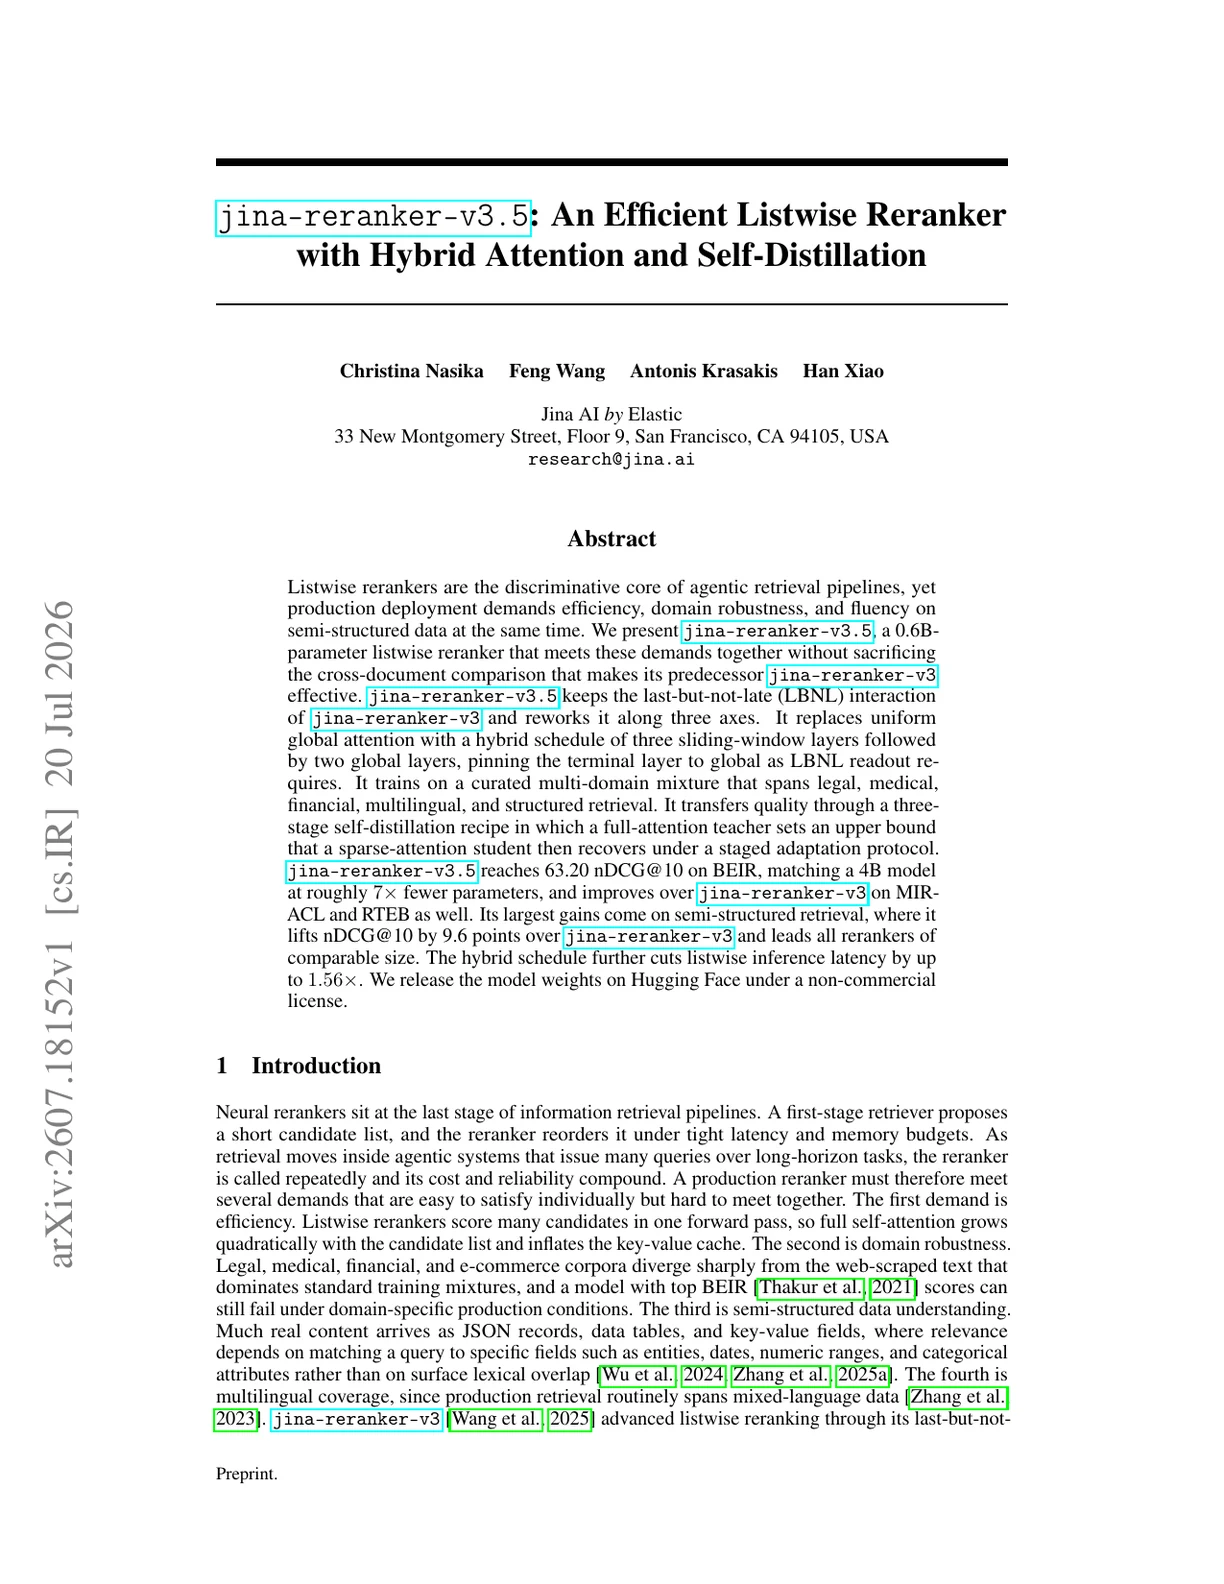
See how our frontier search models were trained from scratch, and check out our latest publications. Meet our team at EMNLP, SIGIR, ICLR, NeurIPS and ICML!
 arXiv
September 02, 2026
 arXiv
July 20, 2026
SIGIR 2026
May 11, 2026
SIGIR 2026
February 17, 2026

ICLR 2026
January 22, 2026
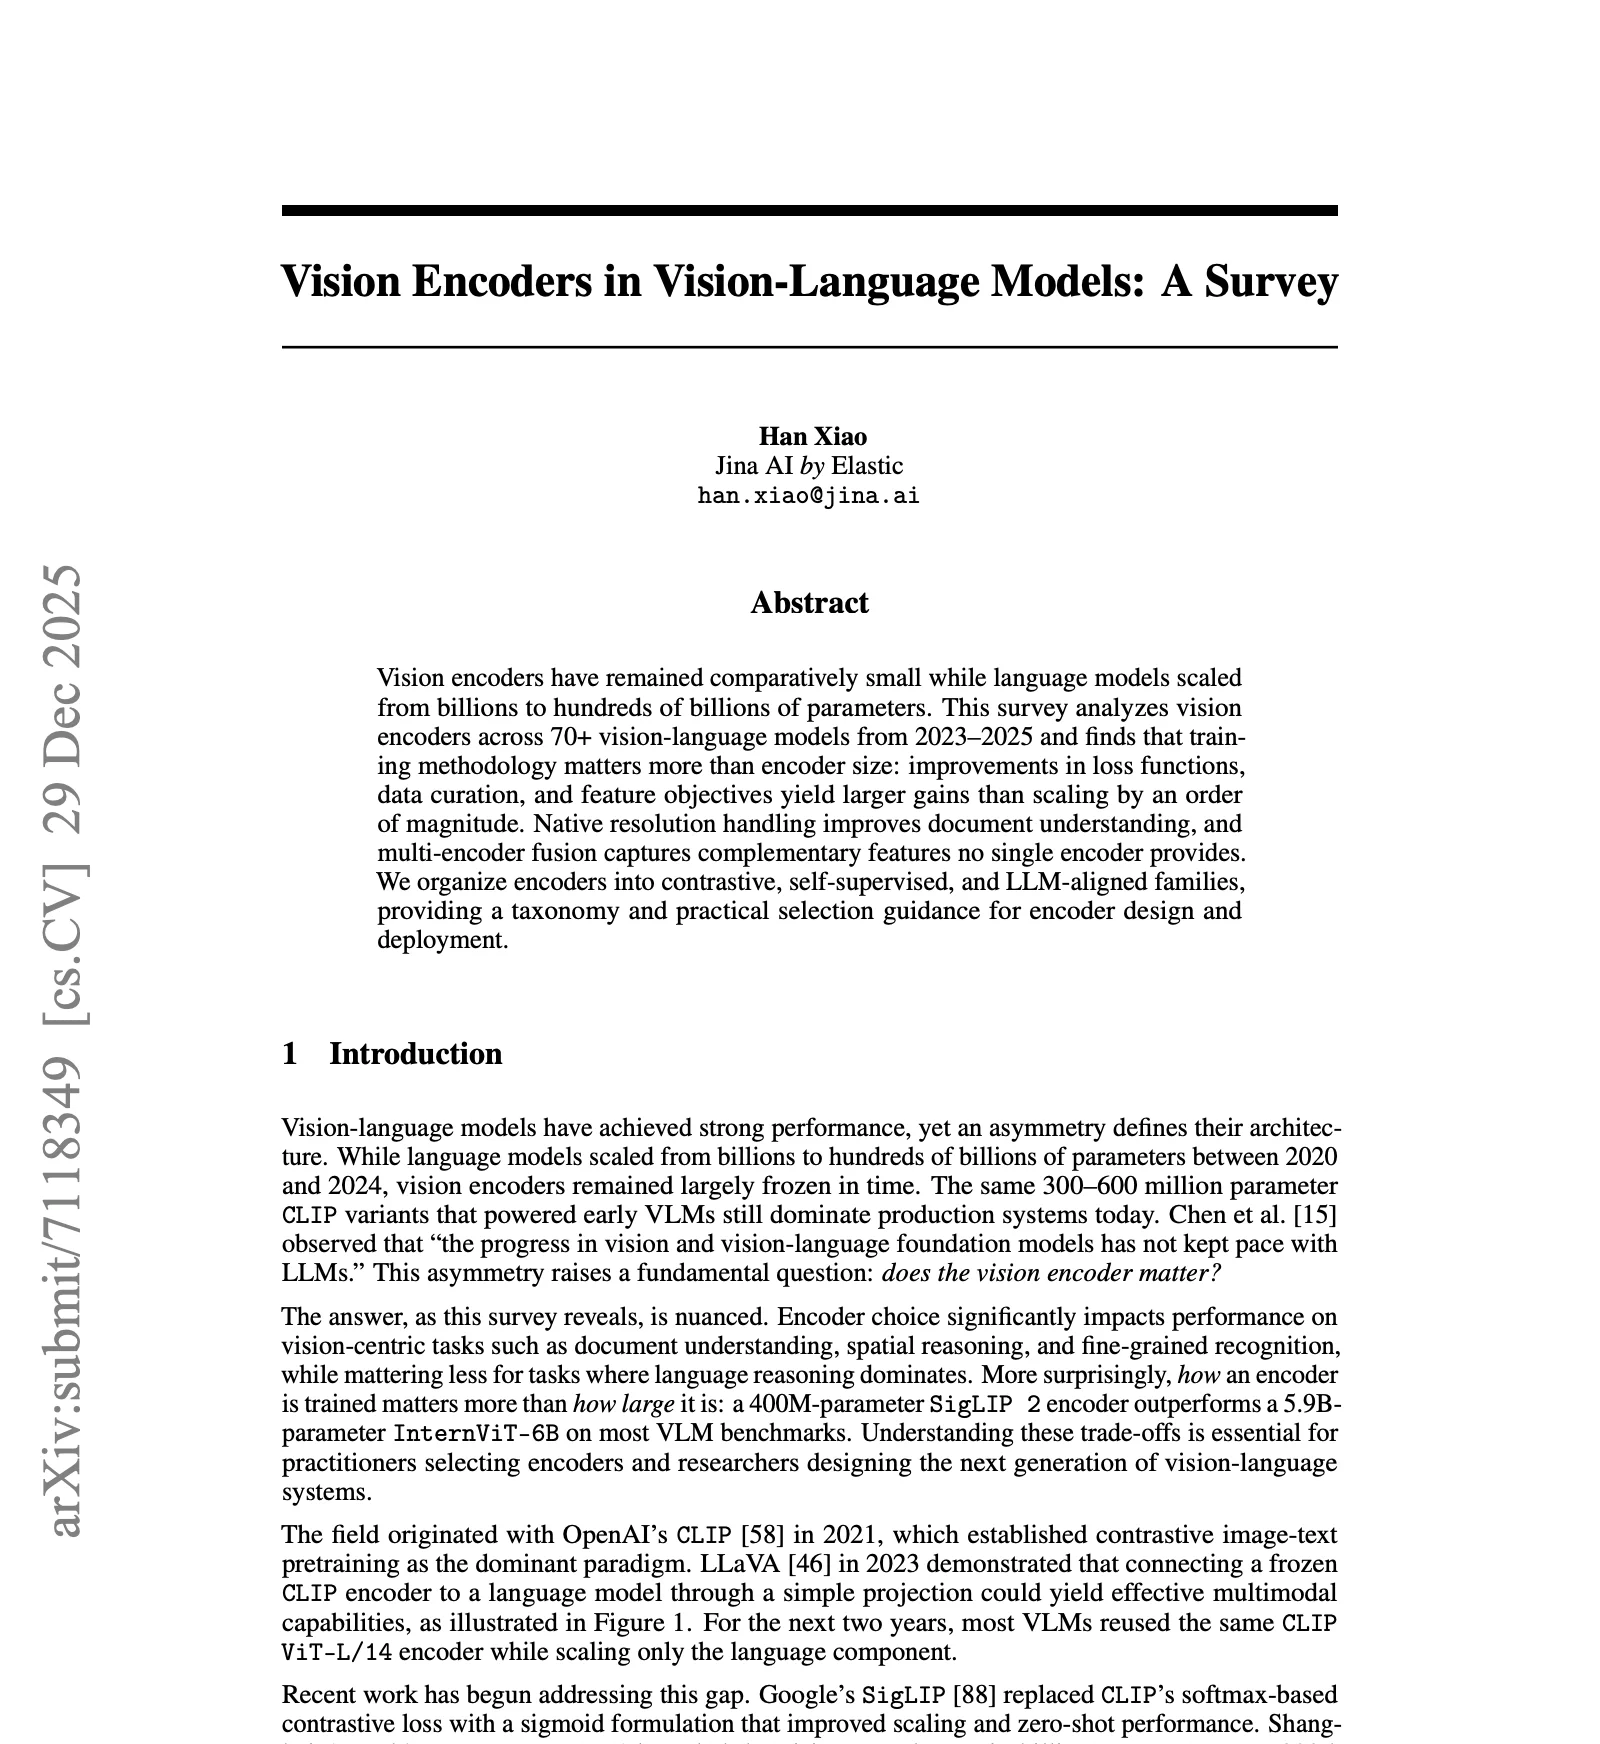 arXiv
December 29, 2025
ICLR 2026
December 04, 2025
AAAI 2026
October 01, 2025
NeurIPS 2025
August 31, 2025
EMNLP 2025
June 24, 2025
ICLR 2025
March 04, 2025
ACL 2025
December 17, 2024
ICLR 2025
December 12, 2024
ECIR 2025
September 18, 2024
SIGIR 2025
September 07, 2024
EMNLP 2024
August 30, 2024
WWW 2025
June 21, 2024
ICML 2024
May 30, 2024
 arXiv
February 26, 2024
 arXiv
October 30, 2023

EMNLP 2023
July 20, 2023
21 publications in total.
Learning about Embeddings
Where to start with embeddings? We've got you covered. Learn about embeddings from the ground up with our comprehensive guide.


Comparison of Reranker, Vector Search, and BM25
The table below provides a comprehensive comparison of the Reranker, Vector/Embeddings Search, and BM25, highlighting their strengths and weaknesses across various categories.
| Reranker | Vector Search | BM25 | |
|---|---|---|---|
| Best For | Enhanced search precision and relevance | Initial, rapid filtering | General text retrieval across wide-ranging queries |
| Granularity | Detailed: Sub-document and query segment | Broad: Entire documents | Intermediate: Various text segments |
| Query Time Complexity | High | Medium | Low |
| Indexing Time Complexity | Not required | High | Low, utilizes pre-built index |
| Training Time Complexity | High | High | Not required |
| Search Quality | Superior for nuanced queries | Balanced between efficiency and accuracy | Consistent and reliable for a broad set of queries |
| Strengths | Highly accurate with deep contextual understanding | Quick and efficient, with moderate accuracy | Highly scalable, with established efficacy |
| Try reranker API for free | Try embedding API for free |
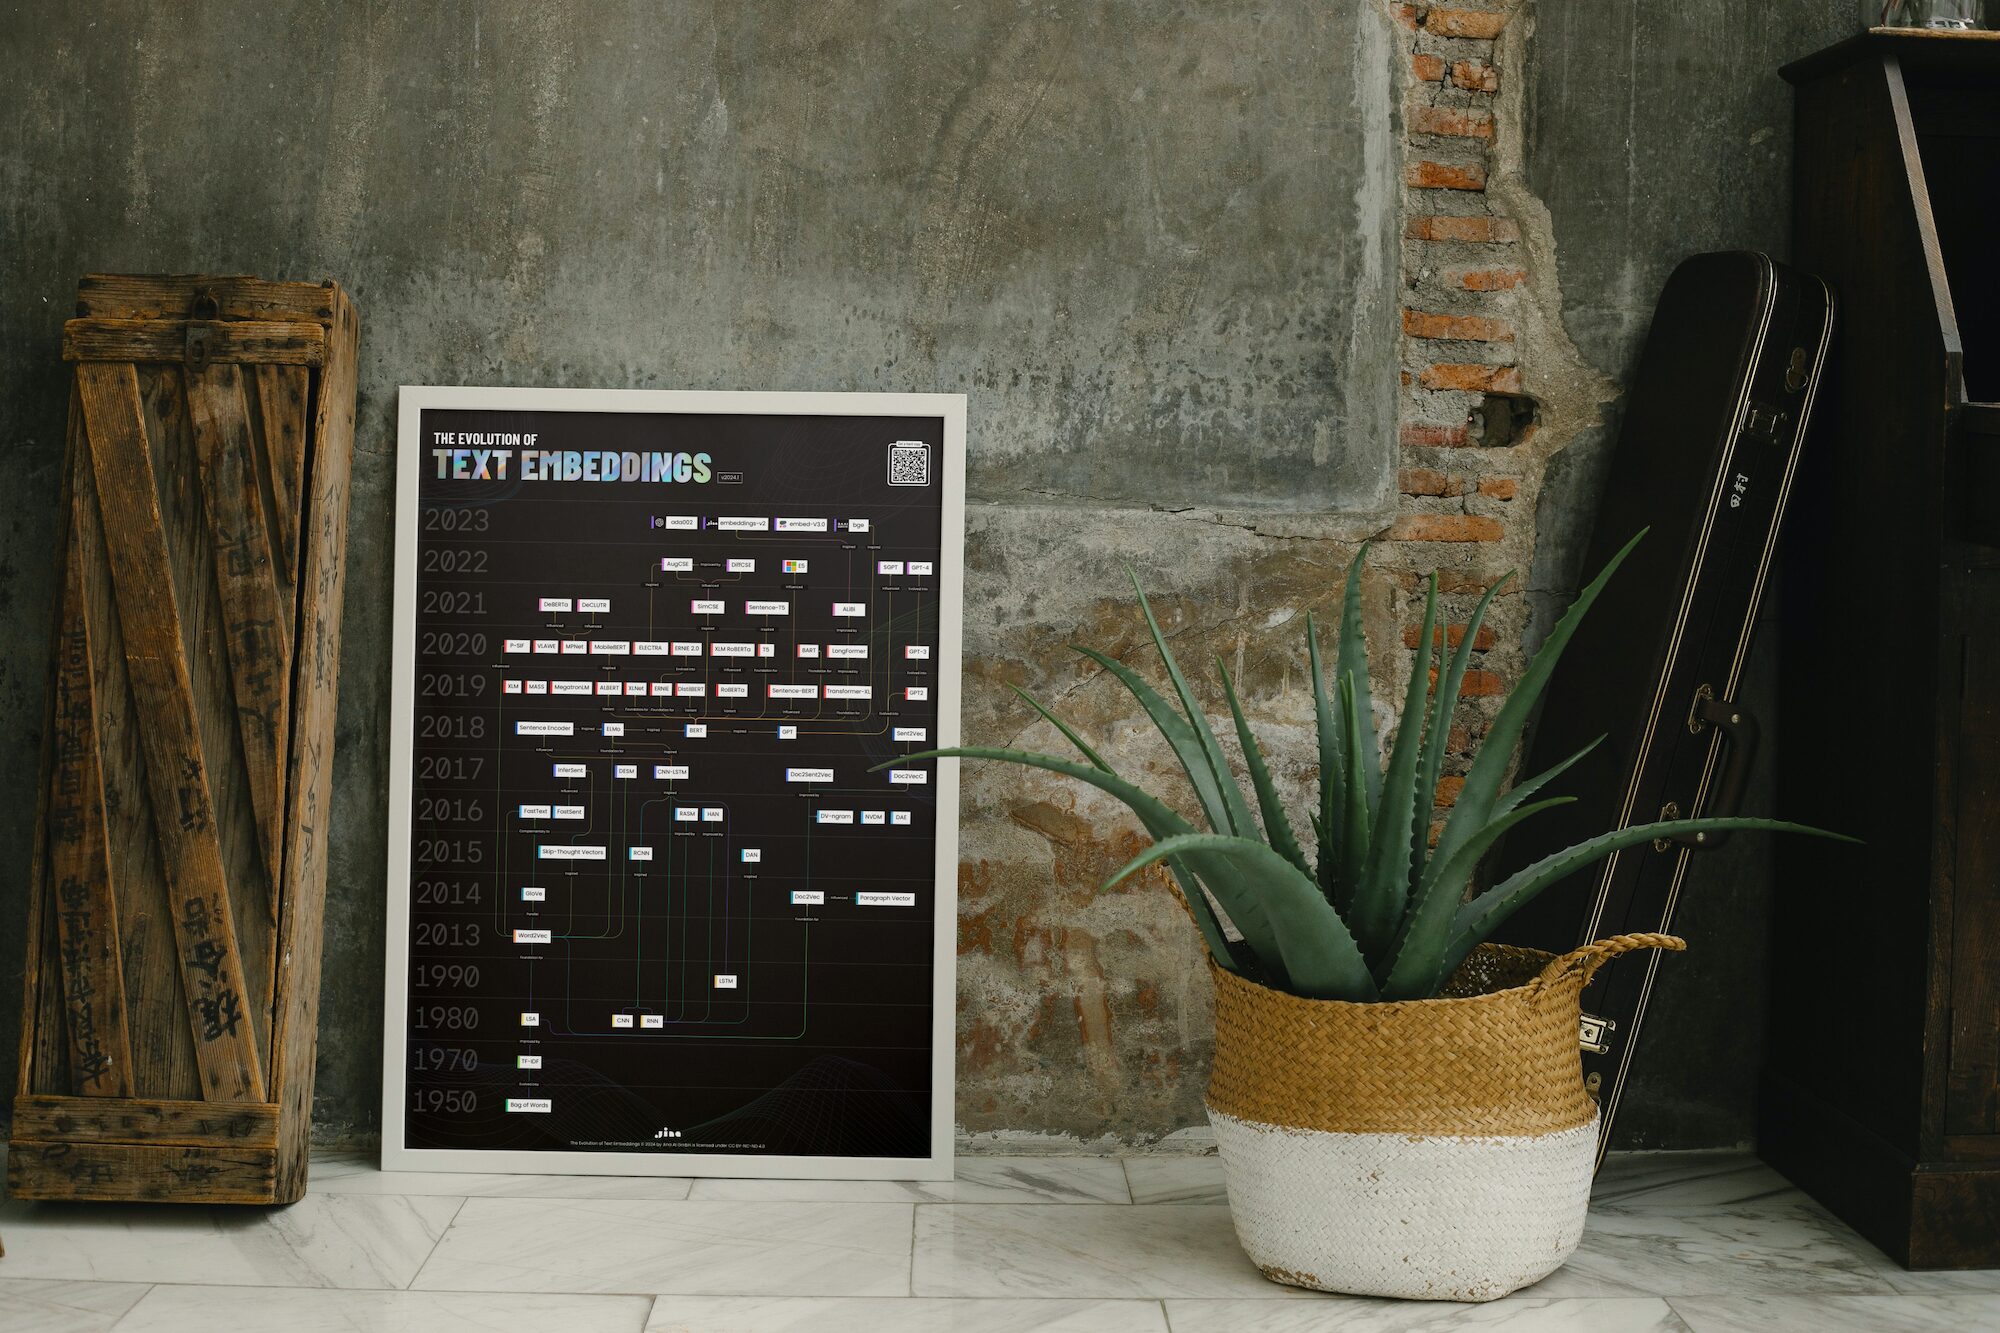
The Evolution of Embeddings Poster
Discover the ideal poster for your space, featuring captivating infographics or breathtaking visuals tracing the evolution of text embedding models since 1950.
How were the Jina embedding models trained?
keyboard_arrow_down
What are your multimodal embedding models?
keyboard_arrow_down
Which languages do your models support?
keyboard_arrow_down
What is the maximum context length for a single input?
keyboard_arrow_down
What is the maximum number of inputs I can include in a single request?
keyboard_arrow_down
How do I send images, audio, video, or PDFs to the multimodal models?
keyboard_arrow_down
How do Jina embeddings compare to the latest OpenAI, Cohere, and Voyage models?
keyboard_arrow_down
How seamless is the transition from OpenAI's text-embedding-3-large to your solution?
keyboard_arrow_down
How are tokens calculated for images and other non-text inputs?
keyboard_arrow_down
Do you provide models for embedding images, audio, or video?
keyboard_arrow_down
Can Jina embedding models be fine-tuned on private or company data?
keyboard_arrow_down
Can the models be hosted privately, on my own infrastructure or in my own cloud account?
keyboard_arrow_down
What is the 'task' parameter and when should I use it?
keyboard_arrow_down
What is late-interaction retrieval and which models support it?
keyboard_arrow_down
What is late chunking and when should I use it?
keyboard_arrow_down
Why does the API enforce a different context length than the model supports?
keyboard_arrow_down
Why is jina-embeddings-v4 free, and why is it slow?
keyboard_arrow_down
What are the rate limits for the Embeddings API?
keyboard_arrow_down
Which embedding model should I choose?
keyboard_arrow_down
What are the file size limits for images and PDFs?
keyboard_arrow_down
Rate limit
Rate limits are tracked in two ways: RPM (requests per minute) and TPM (tokens per minute). Limits are enforced per IP/API key and will be triggered when either the RPM or TPM threshold is reached first. When you provide an API key in the request header, we track rate limits by key rather than IP address.
| Product | API Endpoint | Descriptionarrow_upward | w/o API Keykey_off | w/ Free API Keykey | w/ Paid API Keykey | w/ Premium API Keykey | Average latency | Token Usage Counting | Allowed Request | |
|---|---|---|---|---|---|---|---|---|---|---|
| Reader API | https://r.jina.ai | Converts a URL to LLM-friendly text | 20 RPM | 500 RPM | 500 RPM | trending_up5000 RPM | 7.9s | Count the number of tokens in the output response. | GET/POST | |
| Reader API | https://s.jina.ai | Search the web and convert results to LLM-friendly text | block | 100 RPM | 100 RPM | trending_up1000 RPM | 2.5s | Every request costs a fixed number of tokens, starting from 10,000 tokens | GET/POST | |
| Embedding API | https://api.jina.ai/v1/embeddings | Convert text/images to fixed-length vectors | block | 100 RPM & 100,000 TPM | 500 RPM & 2,000,000 TPM | trending_up5,000 RPM & 50,000,000 TPM | ssid_chart depends on the input size help | Count the number of tokens in the input request. | POST | |
| Reranker API | https://api.jina.ai/v1/rerank | Rank documents by query | block | 100 RPM & 100,000 TPM | 500 RPM & 2,000,000 TPM | trending_up5,000 RPM & 50,000,000 TPM | ssid_chart depends on the input size help | Count the number of tokens in the input request. | POST |
CC BY-NC License Self-Check
play_arrow
Are you using our hosted API, or our official images on Azure, AWS, or GCP?
play_arrow
Yes
play_arrow
No
API-related common questions
code
Can I use the same API key across all Jina APIs?
keyboard_arrow_down
code
Can I monitor the token usage of my API key?
keyboard_arrow_down
code
What should I do if I forget my API key?
keyboard_arrow_down
code
Do API keys expire?
keyboard_arrow_down
code
Can I transfer tokens between API keys?
keyboard_arrow_down
code
Can I revoke my API key?
keyboard_arrow_down
code
Why is the first request for some models slow?
keyboard_arrow_down
code
Is my API data used to train your models?
keyboard_arrow_down
code
What are the rate limits for Jina APIs?
keyboard_arrow_down
code
Are there batch size limits for the APIs?
keyboard_arrow_down
code
Are the Jina APIs the same thing as Jina models inside Elastic?
keyboard_arrow_down
Billing-related common questions
attach_money
Is billing based on the number of sentences or requests?
keyboard_arrow_down
attach_money
Is there a free trial available for new users?
keyboard_arrow_down
attach_money
Are tokens charged for failed requests?
keyboard_arrow_down
attach_money
What payment methods are accepted?
keyboard_arrow_down
attach_money
Is invoicing available for token purchases?
keyboard_arrow_down
attach_money
How do I buy a commercial license rather than API tokens?
keyboard_arrow_down
attach_money
Can I pay by invoice or purchase order instead of card?
keyboard_arrow_down
attach_money
I paid, but my balance or rate limit has not changed. What should I check?
keyboard_arrow_down
attach_money
How do I cancel, stop auto top-up, or remove a saved payment method?
keyboard_arrow_down
