Reader
LM-v2
 Jina API
 AWS SageMaker
 Microsoft Azure
 Google Cloud
 Hugging Face
 Air-gapped
Overview
ReaderLM-v2 is a 1.54B-parameter small language model that transforms messy HTML into clean Markdown or JSON with high accuracy, processing documents up to 512K tokens. It is the ideal tool for grounding large language models: converting web content into structured formats that LLMs can consume efficiently. The model outperforms Qwen2.5-32B-Instruct and Gemini2-flash-expr on HTML-to-Markdown tasks while running at a fraction of their cost.
Methods
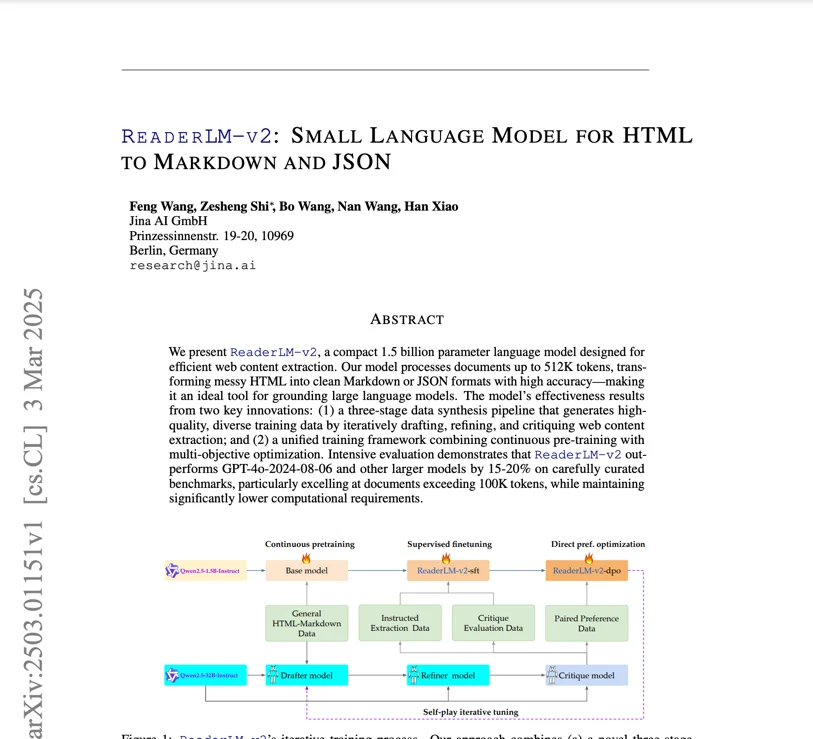
The model's effectiveness results from two key innovations. First, a three-stage data synthesis pipeline generates high-quality, diverse training data by iteratively drafting, refining, and critiquing web content extraction — this synthetic data approach ensures the model sees a wide variety of HTML structures without requiring manual annotation. Second, a unified training framework combines continuous pre-training with multi-objective optimization, allowing the model to learn both HTML-to-Markdown and HTML-to-JSON conversion simultaneously. The 'shallow-but-wide' decoder-only architecture (28 layers, 1536 hidden dimensions, 12 query heads, 2 KV heads) is optimized for selective-copy operations. The 512K token context is enabled through zigzag-ring-attention. Contrastive loss training significantly reduces degeneration issues.
Performance
On HTML-to-Markdown tasks, the model achieves ROUGE-L of 0.84, Jaro-Winkler of 0.82, and Levenshtein distance of 0.22 — outperforming Qwen2.5-32B-Instruct and Gemini2-flash-expr. On HTML-to-JSON tasks, it maintains competitive performance with F1 scores of 0.81 and 98% pass rate. The model processes at 67 tokens/s input and 36 tokens/s output on a T4 GPU. Degeneration issues (token loops, repetitive output) are significantly reduced through contrastive loss training. The 512K token context window eliminates the need for chunking on most real-world documents.
Best Practice
The model is accessible through a Google Colab notebook demonstrating HTML-to-Markdown conversion, JSON extraction, and instruction-following. For HTML-to-Markdown tasks, input raw HTML without prefix instructions. For JSON extraction, specify the target schema in the prompt. The create_prompt helper function facilitates easy prompt creation for both tasks. The model works on Colab's free T4 GPU tier (requires vllm and triton) but has limitations without bfloat16 or Flash Attention 2 support; RTX 3090/4090 is recommended for production. Available on AWS SageMaker, Azure, and GCP marketplace. Licensed under CC BY-NC 4.0 for non-commercial use. Use this model as a preprocessing step in RAG pipelines to convert web content into clean Markdown before embedding with jina-embeddings-v5-text-small.