Embeddings
 Apache 2.0 License
jina-clip-v1
Apache-2.0 Jina API
 AWS SageMaker
 Microsoft Azure
 Hugging Face
 Air-gapped
Overview
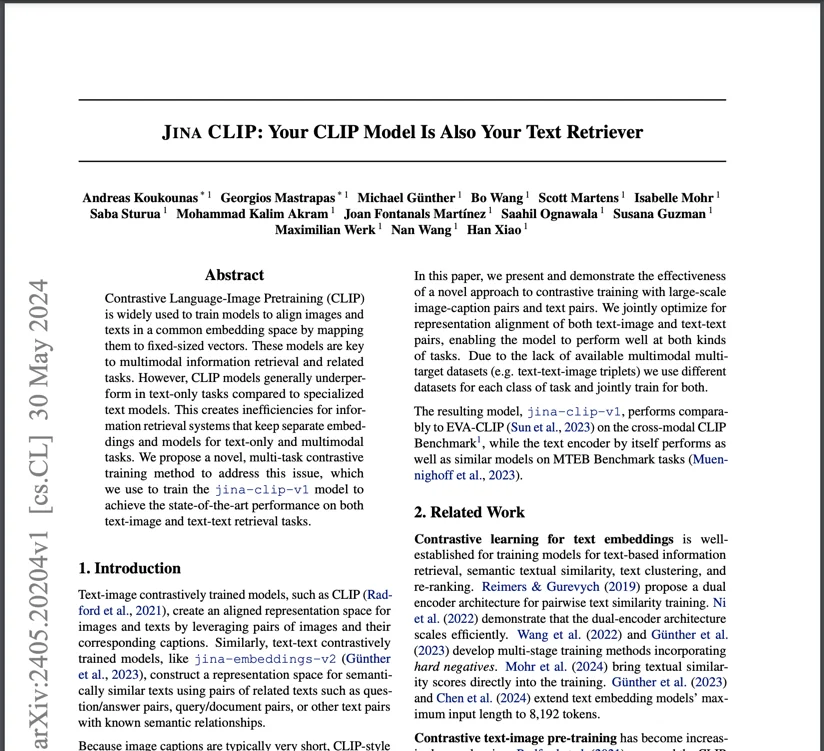
jina-clip-v1 is a 223M-parameter multimodal embedding model that achieves state-of-the-art performance on both text-to-text and text-to-image retrieval tasks — a first among CLIP-family models. Unlike standard CLIP models that sacrifice text-only retrieval for cross-modal alignment, jina-clip-v1 uses multi-task contrastive training to maintain strong performance across all retrieval combinations. It supports 12,288-token text context, 100× the original CLIP's 77-token limit.
Methods
The architecture combines an adapted Jina BERT v2 text encoder (supporting 12,288 tokens via ALiBi) with the EVA-02 image encoder from the Beijing Academy for AI. The key innovation is the multi-task contrastive training method: the model is trained simultaneously on (1) image-caption pairs for cross-modal alignment, (2) text-text pairs to preserve text-only retrieval quality, and (3) AI-generated longer text descriptions of images to improve robustness to varying text lengths. A final stage uses hard negative text triplets to sharpen semantic distinction. This multi-task approach prevents the catastrophic forgetting of text-only retrieval that plagues standard CLIP training. The image encoder processes 224×224 pixel tiles, with each tile consuming 1,000 tokens of processing capacity.
Performance
In text-only retrieval, the model achieves a 165% performance increase over OpenAI CLIP (0.429 vs. 0.162 on MTEB). For image tasks: 2% better in text-to-image retrieval (0.899), 6% in image-to-text retrieval (0.803), and 12% in image-to-image retrieval (0.916). On zero-shot visual classification (CIFAR-100), it outperforms standard CLIP. Cross-modal performance on Flickr8k/30k and MSCOCO Captions is competitive with specialized single-modality models. The 12,288-token text context is a major advantage for retrieving long-form text documents alongside images. In 2026, jina-clip-v2 supersedes this model with 89-language support and 512×512 image processing.
Best Practice
The model processes images in 224×224 pixel tiles; each tile consumes 1,000 tokens. A 750×500 pixel image requires 12 tiles (12,000 tokens). Text requires approximately 1.1 tokens per word. Plan token budgets accordingly for mixed-modal queries. The model currently supports English only — for multilingual applications, use jina-clip-v2. It is available through the Jina Embeddings API and as an open-source release on Hugging Face under the Apache 2.0 license. For production environments, AWS Marketplace and Azure deployment options provide optimized infrastructure. Use cosine similarity for cross-modal comparison. For new multimodal projects, prefer jina-clip-v2 (89 languages, 512×512 images, MRL support) or jina-embeddings-v4 (32K context, multi-vector mode, code support).