

Auto Fine-Tuning
Just tell us which domain you want your embeddings to excel in, and we automatically deliver a ready-to-use, fine-tuned embedding model for that domain.

What is Auto Fine-Tuning?
There are three ways to specify your requirement: a general instruction, a URL, or a query-document description. Choose one.
public
Or, webpage URL
Refer to the content from a URL for fine-tuning.
keyboard_arrow_down
notes
Or, general instruction
Provide a detailed description of how the fine-tuned embeddings will be used.
keyboard_arrow_down
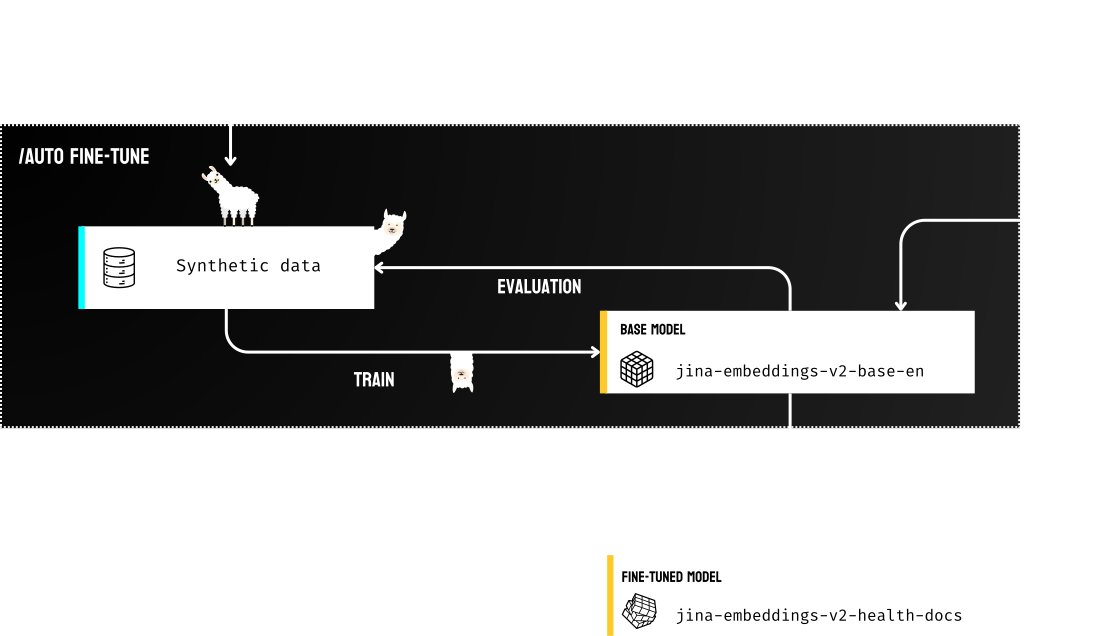
Select a base embedding model


Fine-tuning allows you to take a pre-trained model and adapt it to a specific task or domain by training it on a new dataset. In practice, finding effective training data is not straightforward for many users. Effective training requires more than just throwing raw PDFs, HTMLs into the model; and it is hard to get it right. Auto fine-tuning solves this problem by automatically generating effective training data using an advanced LLM agent pipeline; and fine-tuning the model within a ML workflow. You can think it as a combination of synthetic data generation and AutoML, so all you need to do is describe your target domain in natural language and let our system do the rest.
Auto fine-tuning holds an auto-magical promise to deliver fine-tuned embeddings for any domain you want. But does it really work? This is a fairly reasonable doubt. We've tested it on a variety of domains and base models to find out. Check out the cherry-picked and lemon-picked results below.
Base model for fine-tuning
jinaai/jina-embeddings-v2-base-enAvg. improvement
arrow_upward 2%
description Domain instruction
speed Performance on synthetic validation set before and after fine-tuning
NDCG
0.505 arrow_forward 0.532 arrow_upward 5%
MAP
0.352 arrow_forward 0.389 arrow_upward 10%
MRR
0.352 arrow_forward 0.389 arrow_upward 10%
speed Performance on held-out test set before and after fine-tuning
check
Tested on 50 random samples from tollefj/norwegian-nli-triplets
NDCG
0.852 arrow_forward 0.867 arrow_upward 2%
MAP
0.800 arrow_forward 0.820 arrow_upward 2%
MRR
0.800 arrow_forward 0.820 arrow_upward 2%
data_usage Synthetic data generated
Total
4648
Training
4480
Validation
168
Base model for fine-tuning
jinaai/jina-embeddings-v2-base-enAvg. improvement
arrow_upward 6%
description Domain instruction
speed Performance on synthetic validation set before and after fine-tuning
NDCG
0.672 arrow_forward 0.755 arrow_upward 12%
MAP
0.567 arrow_forward 0.675 arrow_upward 19%
MRR
0.567 arrow_forward 0.675 arrow_upward 19%
speed Performance on held-out test set before and after fine-tuning
check
Tested on 50 random samples from mteb/askubuntudupquestions-reranking
NDCG
0.698 arrow_forward 0.722 arrow_upward 3%
MAP
0.515 arrow_forward 0.549 arrow_upward 6%
MRR
0.666 arrow_forward 0.712 arrow_upward 7%
data_usage Synthetic data generated
Total
616
Training
448
Validation
168
Base model for fine-tuning
jinaai/jina-embeddings-v2-base-enAvg. improvement
arrow_upward 9%
description Domain instruction
speed Performance on synthetic validation set before and after fine-tuning
NDCG
0.727 arrow_forward 0.861 arrow_upward 18%
MAP
0.640 arrow_forward 0.814 arrow_upward 27%
MRR
0.640 arrow_forward 0.814 arrow_upward 27%
speed Performance on held-out test set before and after fine-tuning
check
Tested on 50 random samples from mteb/scidocs-reranking
NDCG
0.773 arrow_forward 0.822 arrow_upward 6%
MAP
0.575 arrow_forward 0.651 arrow_upward 13%
MRR
0.823 arrow_forward 0.884 arrow_upward 7%
data_usage Synthetic data generated
Total
616
Training
448
Validation
168
Base model for fine-tuning
jinaai/jina-embeddings-v2-base-zhAvg. improvement
arrow_upward 1%
description Domain instruction
speed Performance on synthetic validation set before and after fine-tuning
NDCG
0.718 arrow_forward 0.785 arrow_upward 9%
MAP
0.629 arrow_forward 0.717 arrow_upward 14%
MRR
0.629 arrow_forward 0.717 arrow_upward 14%
speed Performance on held-out test set before and after fine-tuning
check
Tested on 50 random samples from C-MTEB/CMedQAv2-reranking
NDCG
0.938 arrow_forward 0.948 arrow_upward 1%
MAP
0.912 arrow_forward 0.926 arrow_upward 2%
MRR
0.920 arrow_forward 0.933 arrow_upward 1%
data_usage Synthetic data generated
Total
616
Training
448
Validation
168
Base model for fine-tuning
jinaai/jina-embeddings-v2-base-enAvg. improvement
arrow_upward 6%
description Domain instruction
speed Performance on synthetic validation set before and after fine-tuning
NDCG
0.543 arrow_forward 0.579 arrow_upward 7%
MAP
0.402 arrow_forward 0.452 arrow_upward 12%
MRR
0.402 arrow_forward 0.452 arrow_upward 12%
speed Performance on held-out test set before and after fine-tuning
check
Tested on 50 random samples from nc33/triplet_sbert_law2 (machine-translated to dutch)
NDCG
0.904 arrow_forward 0.948 arrow_upward 5%
MAP
0.870 arrow_forward 0.930 arrow_upward 7%
MRR
0.870 arrow_forward 0.930 arrow_upward 7%
data_usage Synthetic data generated
Total
9128
Training
8960
Validation
168
Base model for fine-tuning
jinaai/jina-embeddings-v2-base-codeAvg. improvement
arrow_downward -4%
description Domain instruction
speed Performance on synthetic validation set before and after fine-tuning
NDCG
0.671 arrow_forward 0.640 arrow_downward -5%
MAP
0.569 arrow_forward 0.525 arrow_downward -8%
MRR
0.569 arrow_forward 0.525 arrow_downward -8%
speed Performance on held-out test set before and after fine-tuning
check
Tested on 50 random samples from mteb/stackoverflowdupquestions-reranking
NDCG
0.640 arrow_forward 0.621 arrow_downward -3%
MAP
0.530 arrow_forward 0.505 arrow_downward -5%
MRR
0.555 arrow_forward 0.532 arrow_downward -4%
data_usage Synthetic data generated
Total
616
Training
448
Validation
168
Base model for fine-tuning
jinaai/jina-embeddings-v2-base-codeAvg. improvement
arrow_downward -4%
description Domain instruction
speed Performance on synthetic validation set before and after fine-tuning
NDCG
0.632 arrow_forward 0.711 arrow_upward 13%
MAP
0.517 arrow_forward 0.622 arrow_upward 20%
MRR
0.517 arrow_forward 0.622 arrow_upward 20%
speed Performance on held-out test set before and after fine-tuning
check
Tested on 50 random samples from mteb/stackoverflowdupquestions-reranking
NDCG
0.640 arrow_forward 0.619 arrow_downward -3%
MAP
0.530 arrow_forward 0.504 arrow_downward -5%
MRR
0.555 arrow_forward 0.525 arrow_downward -5%
data_usage Synthetic data generated
Total
616
Training
448
Validation
168
Base model for fine-tuning
jinaai/jina-embeddings-v2-base-enAvg. improvement
arrow_upward 1%
description Domain instruction
speed Performance on synthetic validation set before and after fine-tuning
NDCG
0.646 arrow_forward 0.729 arrow_upward 13%
MAP
0.535 arrow_forward 0.644 arrow_upward 20%
MRR
0.535 arrow_forward 0.644 arrow_upward 20%
speed Performance on held-out test set before and after fine-tuning
check
Tested on 50 random samples from mteb/askubuntudupquestions-reranking
NDCG
0.645 arrow_forward 0.650 arrow_upward 1%
MAP
0.452 arrow_forward 0.462 arrow_upward 2%
MRR
0.606 arrow_forward 0.605 arrow_downward -0%
data_usage Synthetic data generated
Total
616
Training
448
Validation
168
Auto Fine-Tuning API
Get fine-tuned embeddings for any domain you want.
globe_book
Use
r.jina.ai to read a URL and fetch its contenttravel_explore
Use
s.jina.ai to search the web and get SERP
Add
mcp.jina.ai as your MCP server to use our APIs in LLMscurl "https://r.jina.ai/https://www.example.com"code
Can I use the same API key across all Jina APIs?
keyboard_arrow_down
code
Can I monitor the token usage of my API key?
keyboard_arrow_down
code
What should I do if I forget my API key?
keyboard_arrow_down
code
Do API keys expire?
keyboard_arrow_down
code
Can I transfer tokens between API keys?
keyboard_arrow_down
code
Can I revoke my API key?
keyboard_arrow_down
code
Why is the first request for some models slow?
keyboard_arrow_down
code
Is my API data used to train your models?
keyboard_arrow_down
code
What are the rate limits for Jina APIs?
keyboard_arrow_down
code
Are there batch size limits for the APIs?
keyboard_arrow_down
code
Are the Jina APIs the same thing as Jina models inside Elastic?
keyboard_arrow_down
Rate limit
Rate limits are tracked in two ways: RPM (requests per minute) and TPM (tokens per minute). Limits are enforced per IP/API key and will be triggered when either the RPM or TPM threshold is reached first. When you provide an API key in the request header, we track rate limits by key rather than IP address.
| Product | API Endpoint | Descriptionarrow_upward | w/o API Keykey_off | w/ Free API Keykey | w/ Paid API Keykey | w/ Premium API Keykey | Average latency | Token Usage Counting | Allowed Request | |
|---|---|---|---|---|---|---|---|---|---|---|
| Reader API | https://r.jina.ai | Converts a URL to LLM-friendly text | 20 RPM | 500 RPM | 500 RPM | trending_up5000 RPM | 7.9s | Count the number of tokens in the output response. | GET/POST | |
| Reader API | https://s.jina.ai | Search the web and convert results to LLM-friendly text | block | 100 RPM | 100 RPM | trending_up1000 RPM | 2.5s | Every request costs a fixed number of tokens, starting from 10,000 tokens | GET/POST | |
| Embedding API | https://api.jina.ai/v1/embeddings | Convert text/images to fixed-length vectors | block | 100 RPM & 100,000 TPM | 500 RPM & 2,000,000 TPM | trending_up5,000 RPM & 50,000,000 TPM | ssid_chart depends on the input size help | Count the number of tokens in the input request. | POST | |
| Reranker API | https://api.jina.ai/v1/rerank | Rank documents by query | block | 100 RPM & 100,000 TPM | 500 RPM & 2,000,000 TPM | trending_up5,000 RPM & 50,000,000 TPM | ssid_chart depends on the input size help | Count the number of tokens in the input request. | POST |


Billing-related common questions
attach_money
Is billing based on the number of sentences or requests?
keyboard_arrow_down
attach_money
Is there a free trial available for new users?
keyboard_arrow_down
attach_money
Are tokens charged for failed requests?
keyboard_arrow_down
attach_money
What payment methods are accepted?
keyboard_arrow_down
attach_money
Is invoicing available for token purchases?
keyboard_arrow_down
attach_money
How do I buy a commercial license rather than API tokens?
keyboard_arrow_down
attach_money
Can I pay by invoice or purchase order instead of card?
keyboard_arrow_down
attach_money
I paid, but my balance or rate limit has not changed. What should I check?
keyboard_arrow_down
attach_money
How do I cancel, stop auto top-up, or remove a saved payment method?
keyboard_arrow_down