Embeddings
jina-embeddings-v5-omni-nano
 GGUF
 MLX
 Elastic Inference Service
 Jina API
 AWS SageMaker
 Hugging Face
 MacOS
 Air-gapped
Overview
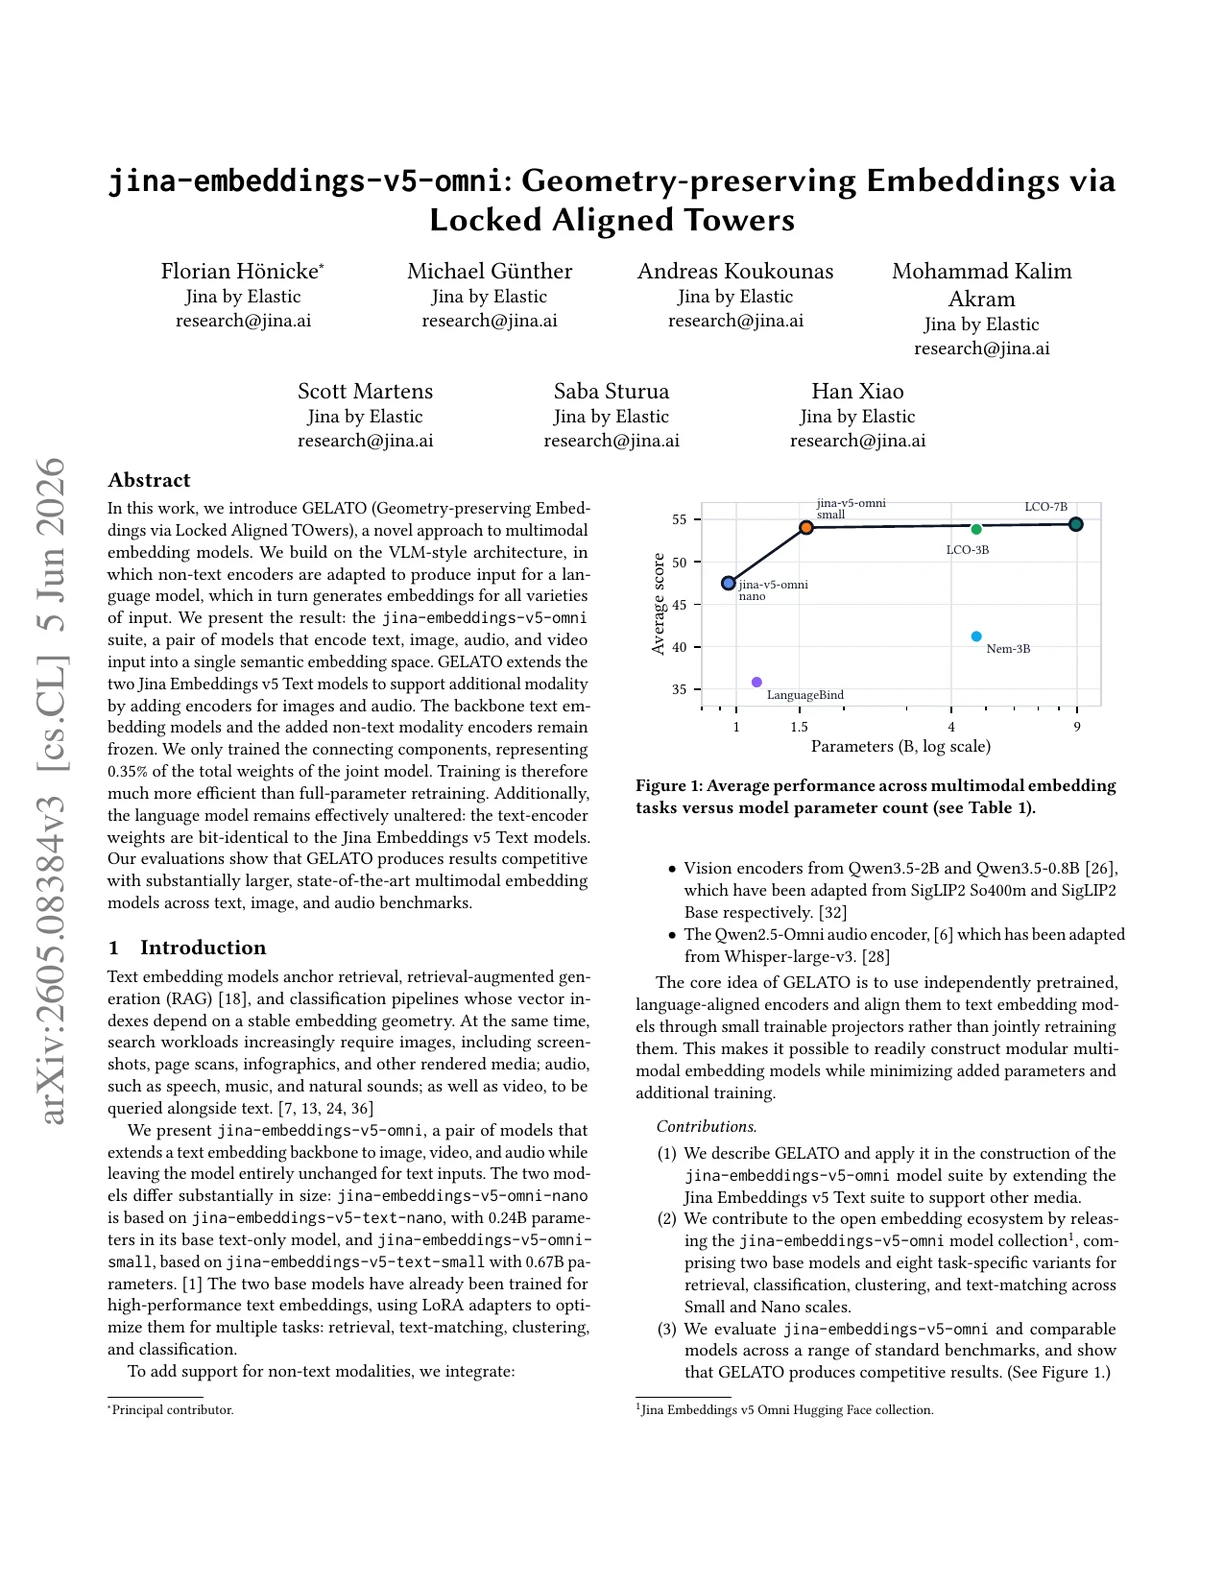
jina-embeddings-v5-omni-nano is a ~1.04B-parameter multimodal embedding model that accepts text, images, video, and audio, producing embeddings in a shared vector space. It is the compact variant of the v5-omni family, designed for edge and commodity hardware where a GPU is unavailable. Text-only outputs are bit-identical to jina-embeddings-v5-text-nano, making it a drop-in upgrade from text-only to multimodal without reindexing.
Methods
The model extends jina-embeddings-v5-text-nano with multimodal capabilities via a third training stage. The EuroBERT-210M text backbone and all four task-specific LoRA adapters are frozen; only the cross-modal projectors are newly trained. A SigLIP2 Base vision encoder handles images and video (32 uniformly sampled frames per video). A Whisper-large-v3 audio encoder handles audio input. PDF pages are rendered as images and processed through the vision pathway. Training uses contrastive loss with cross-modal hard negatives to align visual and audio representations with the existing text embedding space. The 768-dimensional output space supports Matryoshka truncation down to 32 dimensions. The 8K token context window covers text input; image and audio inputs are processed through their respective encoders.
Performance
Text-only performance is bit-identical to jina-embeddings-v5-text-nano (65.5 MMTEB task-level average, 71.0 English MTEB). Multimodal performance is slightly below jina-embeddings-v5-omni-small due to the narrower 768-dimensional embedding space (vs. 1024) and smaller text backbone, but maintains strong cross-modal alignment across text-image, text-audio, and text-video retrieval. The model is optimized for CPU and edge hardware, where the larger omni-small model cannot run efficiently. Cross-modal retrieval quality is competitive for its size class.
Best Practice
Same usage pattern as jina-embeddings-v5-omni-small: select the appropriate LoRA adapter (retrieval, text-matching, clustering, classification) and pass image URLs, audio file URLs, video file URLs, or PDF URLs directly via the API — the model routes each modality through the appropriate encoder. Supported audio formats: WAV, MP3, FLAC, OGG, M4A, Opus. Video inputs are processed as 32 uniformly sampled frames. Mix modalities freely within a single batch; the embedding space is shared across all modalities. Use cosine similarity for comparison. Matryoshka truncation from 768 to 32 dimensions is supported. Text-only embeddings are drop-in compatible with jina-embeddings-v5-text-nano — no reindexing needed when upgrading. For server deployments requiring higher accuracy, use jina-embeddings-v5-omni-small (1024 dimensions, larger backbone).