Embeddings
jina-embeddings-v5-omni-small
 GGUF
 MLX
 Elastic Inference Service
 Jina API
 AWS SageMaker
 Hugging Face
 MacOS
 Air-gapped
Overview
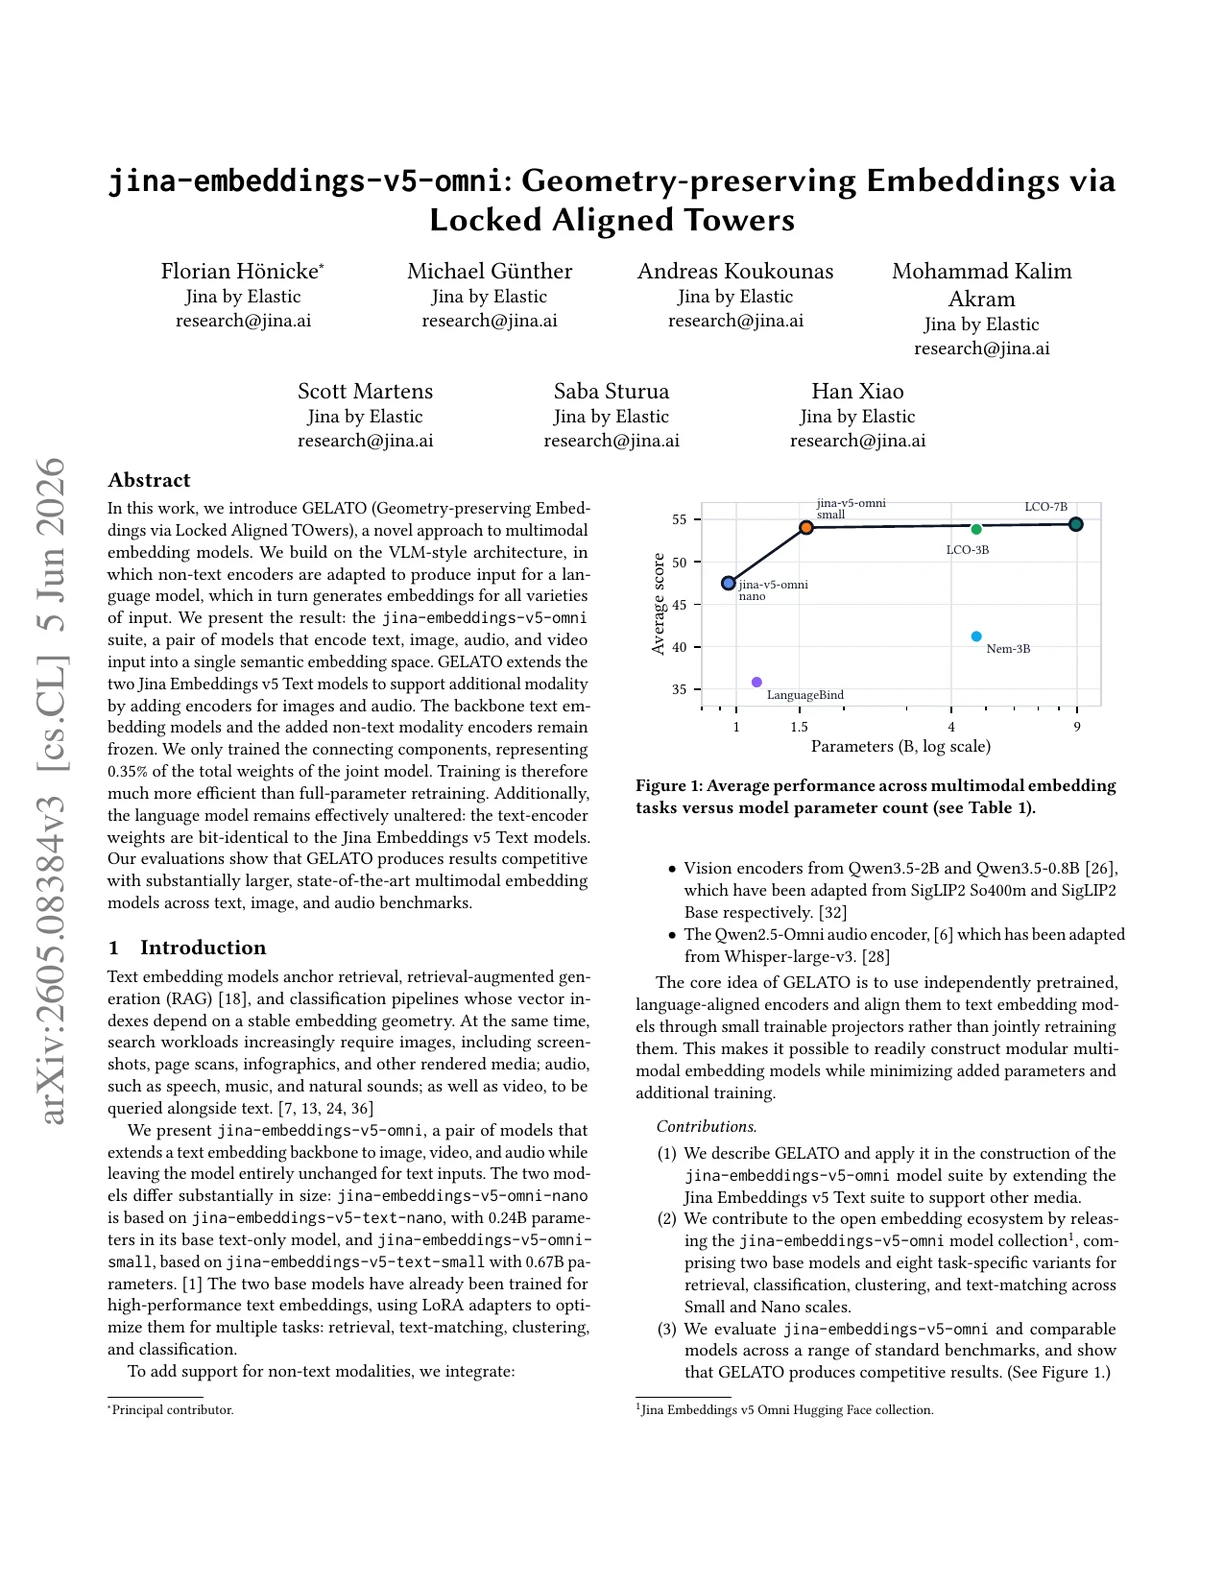
jina-embeddings-v5-omni-small is a ~1.74B-parameter multimodal embedding model that accepts text, images, video, audio, and PDF, producing embeddings in a shared 1024-dimensional vector space. It is the default embedding model for Jina's API and offers the best accuracy-efficiency tradeoff among Jina's multimodal embedding models. Text-only outputs are bit-identical to jina-embeddings-v5-text-small, enabling seamless migration from text-only to multimodal without reindexing.
Methods
The model is trained in a third stage extending jina-embeddings-v5-text-small. The Qwen3-0.6B-Base text backbone and all four task-specific LoRA adapters are frozen during multimodal training; only the cross-modal projectors are newly trained. A SigLIP2 Large vision encoder handles images and video (32 uniformly sampled frames per video). A Whisper-large-v3 audio encoder handles audio input. PDF pages are rendered as images and processed through the vision pathway. Training uses contrastive loss with cross-modal hard negatives to align visual and audio representations with the existing text embedding space. The 1024-dimensional output supports Matryoshka truncation down to 32 dimensions. The 32K token context window covers text input. The model supports quantized and MLX inference for Apple Silicon.
Performance
Text-only performance is bit-identical to jina-embeddings-v5-text-small (67.0 MMTEB task-level average, 71.7 English MTEB) — the text backbone and LoRA adapters are untouched during multimodal training. On cross-modal retrieval, the model demonstrates strong alignment across text-image, text-audio, and text-video tasks. PDF page retrieval is handled through the vision pathway. The omni-small model offers the best accuracy-efficiency tradeoff among Jina multimodal embedding models for server deployment, with 1024-dimensional embeddings providing more discriminative power than the 768-dimensional omni-nano variant.
Best Practice
Select the appropriate LoRA adapter: retrieval, text-matching, clustering, or classification. For multimodal inputs via the API, pass image URLs, audio file URLs, video file URLs, or PDF URLs directly — the model routes each modality through the appropriate encoder. Supported audio formats include WAV, MP3, FLAC, OGG, M4A, and Opus. Video inputs are processed as 32 uniformly sampled frames. Mix modalities freely within a single batch: the embedding space is shared across all modalities. Use cosine similarity for comparison. Matryoshka truncation from 1024 to 32 dimensions is supported. Text-only embeddings are drop-in compatible with jina-embeddings-v5-text-small — no reindexing needed when upgrading. For edge deployments without GPU, use jina-embeddings-v5-omni-nano instead.