News

Accelerate search AI, one token at a time.

RSS
Featured
Academic Publications
arXiv
September 02, 2026
jina-ocr-v1: Efficient Document Parsing with Speculative Decoding and Dense Verifiable Rewards
arXiv
July 20, 2026
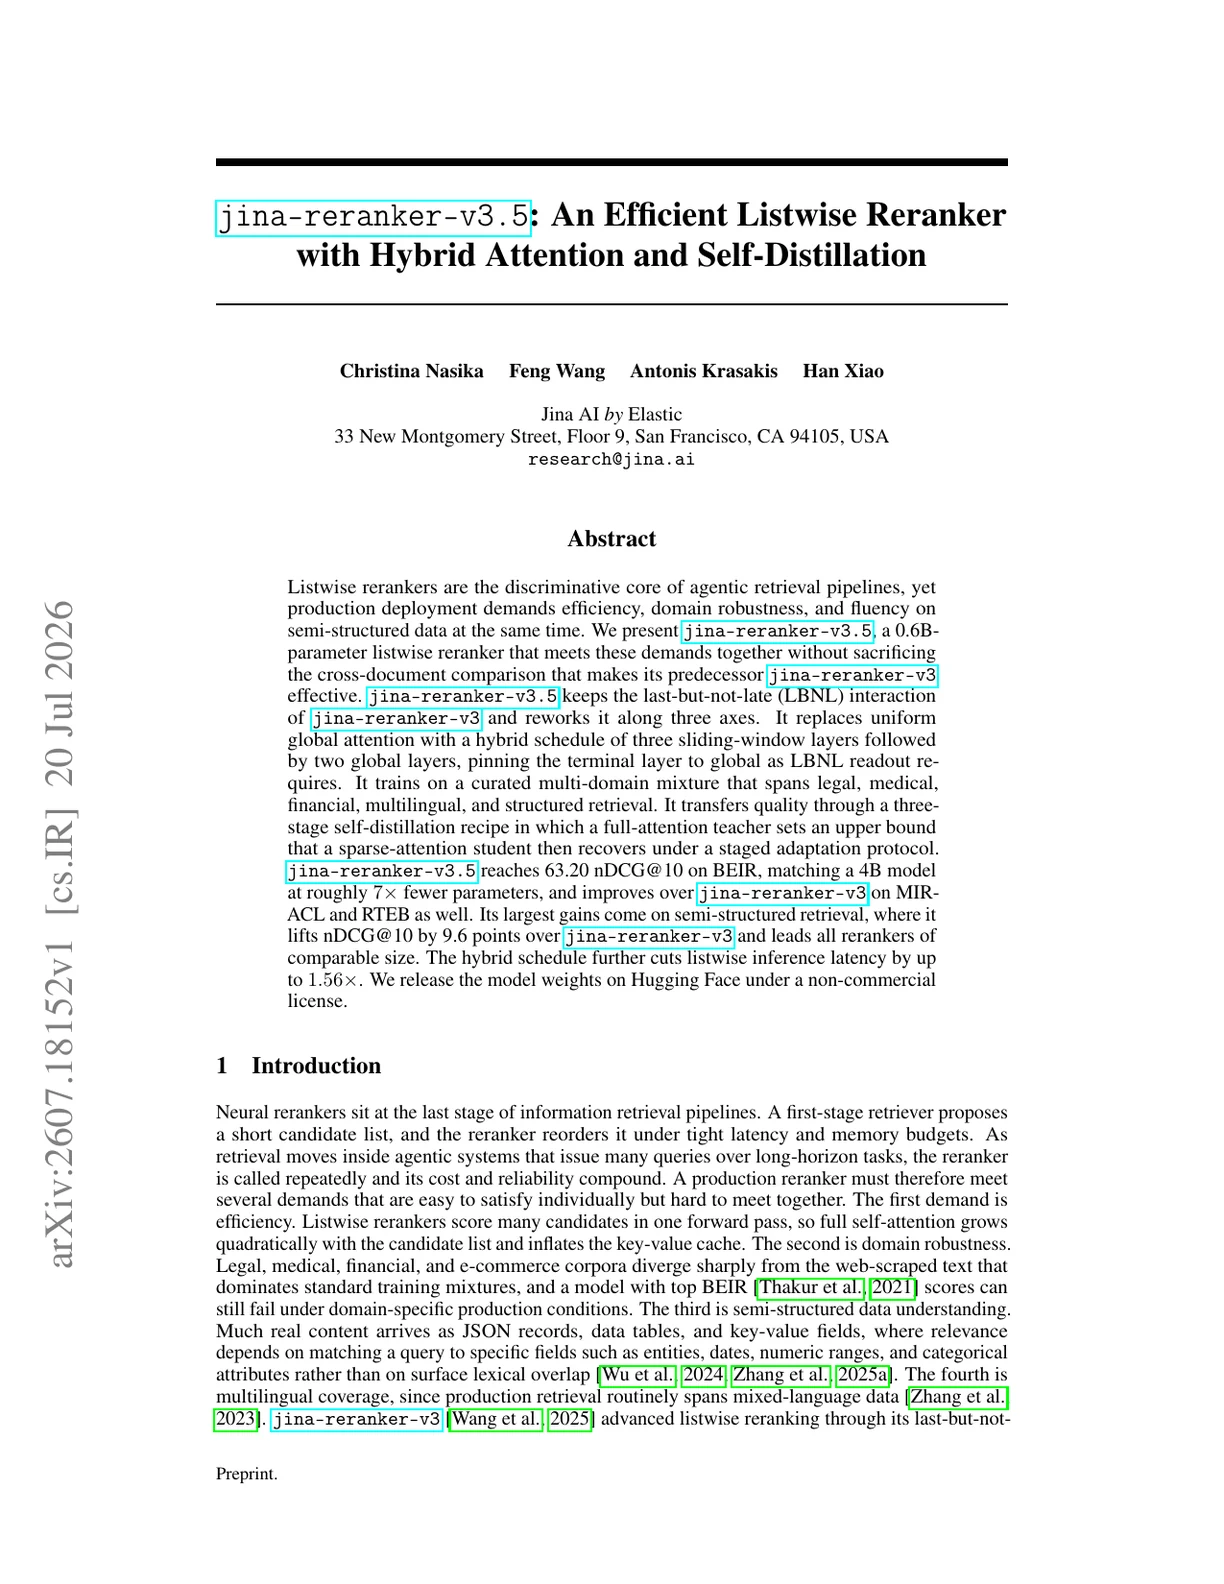
jina-reranker-v3.5: An Efficient Listwise Reranker with Hybrid Attention and Self-Distillation
SIGIR 2026
May 11, 2026
jina-embeddings-v5-omni: Geometry-preserving Embeddings via Locked Aligned Towers
SIGIR 2026
February 17, 2026
jina-embeddings-v5-text: Task-Targeted Embedding Distillation
ICLR 2026
January 22, 2026
Embedding Compression via Spherical Coordinates
arXiv
December 29, 2025
Vision Encoders in Vision-Language Models: A Survey
ICLR 2026
December 04, 2025
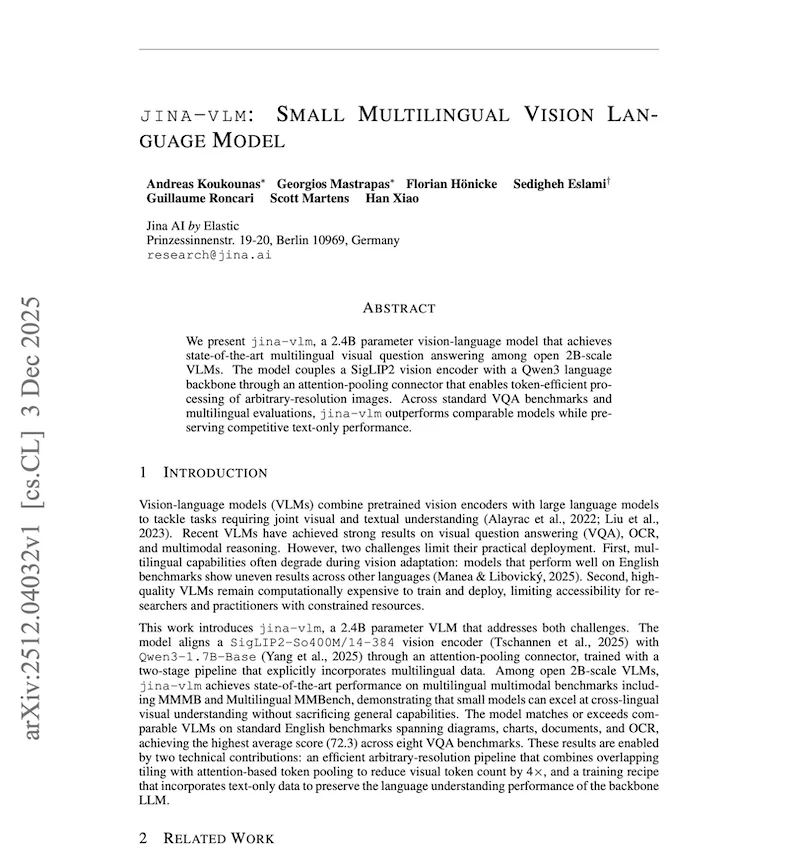
Jina-VLM: Small Multilingual Vision Language Model
AAAI 2026
October 01, 2025
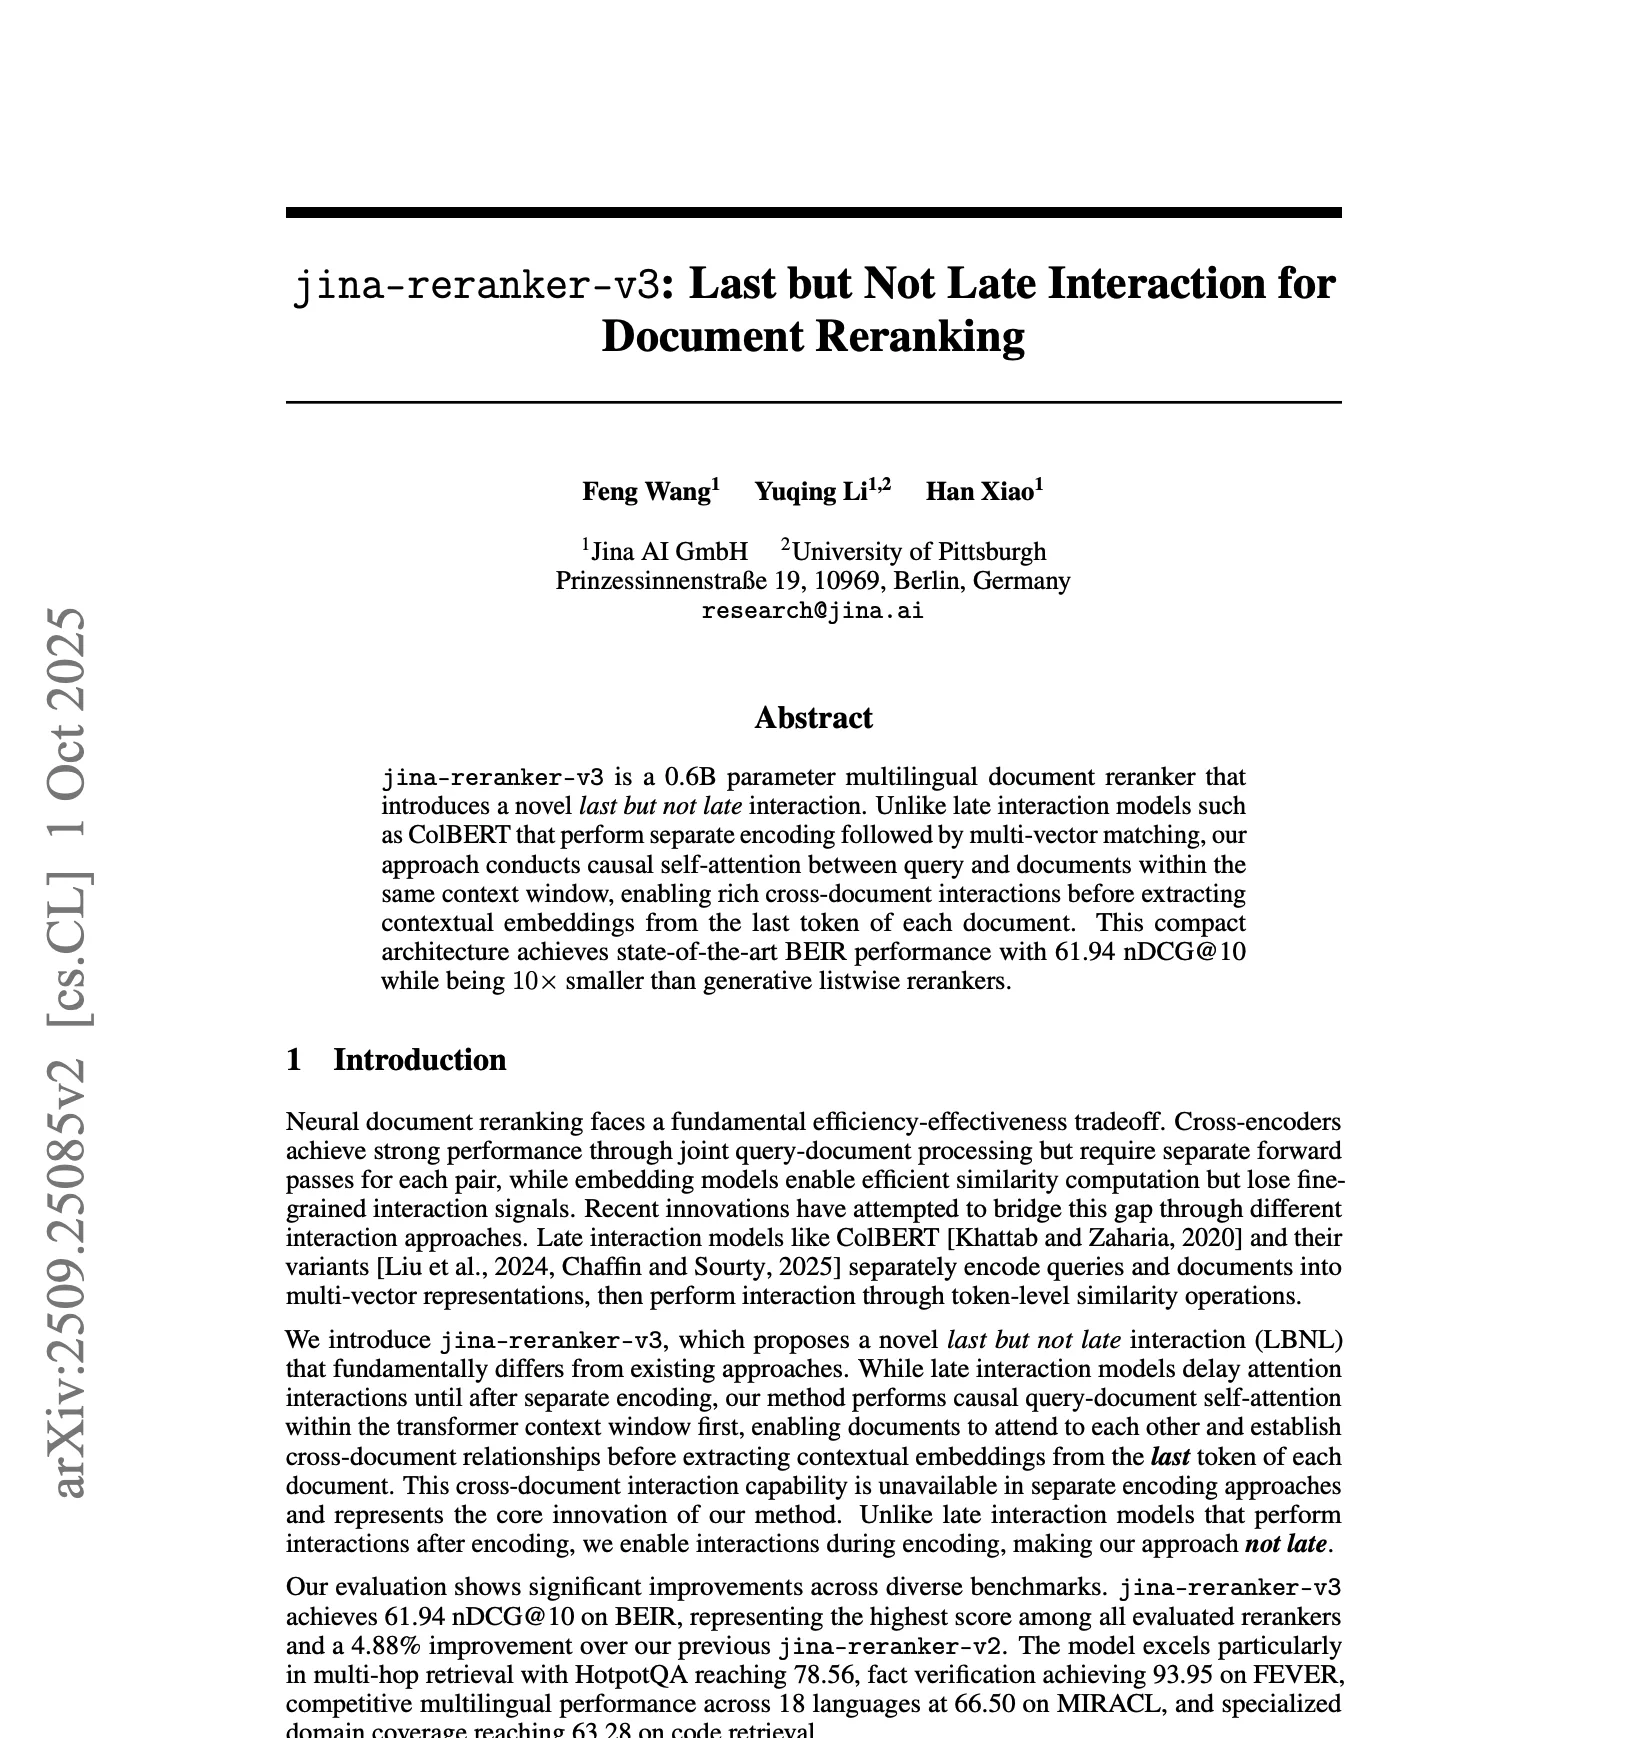
jina-reranker-v3: Last but Not Late Interaction for Document Reranking
NeurIPS 2025
August 31, 2025
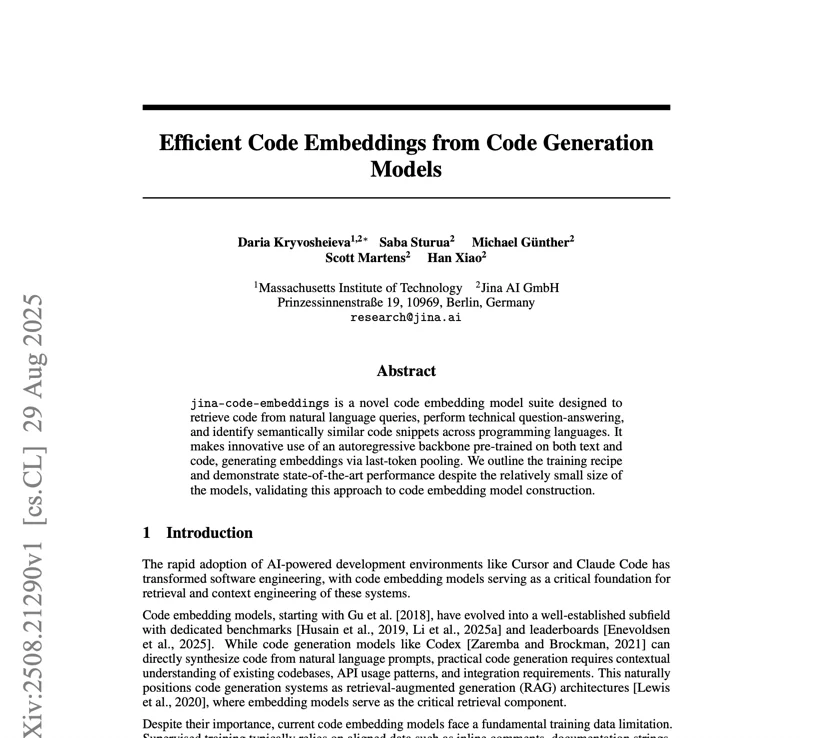
Efficient Code Embeddings from Code Generation Models
EMNLP 2025
June 24, 2025
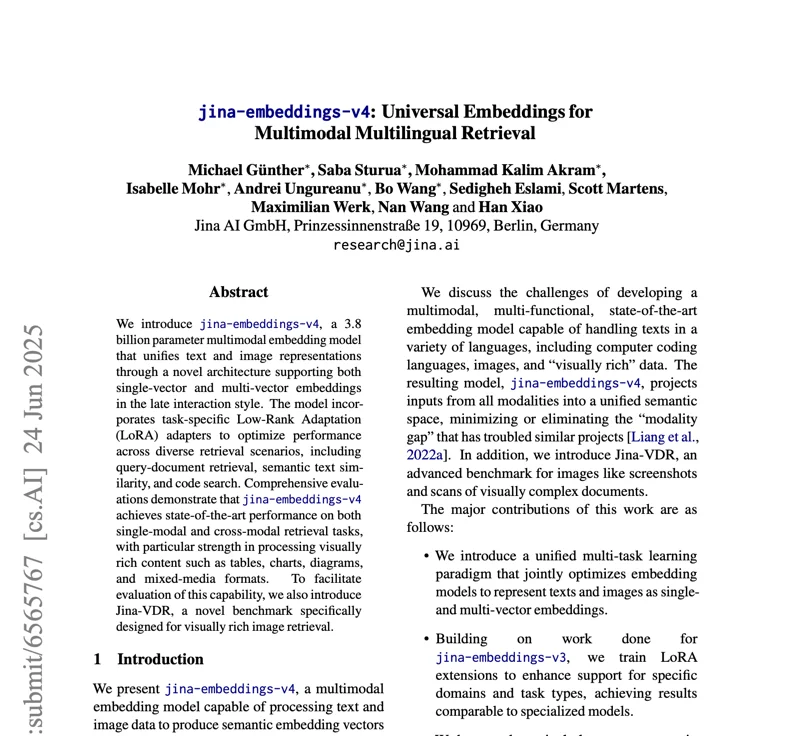
jina-embeddings-v4: Universal Embeddings for Multimodal Multilingual Retrieval
ICLR 2025
March 04, 2025
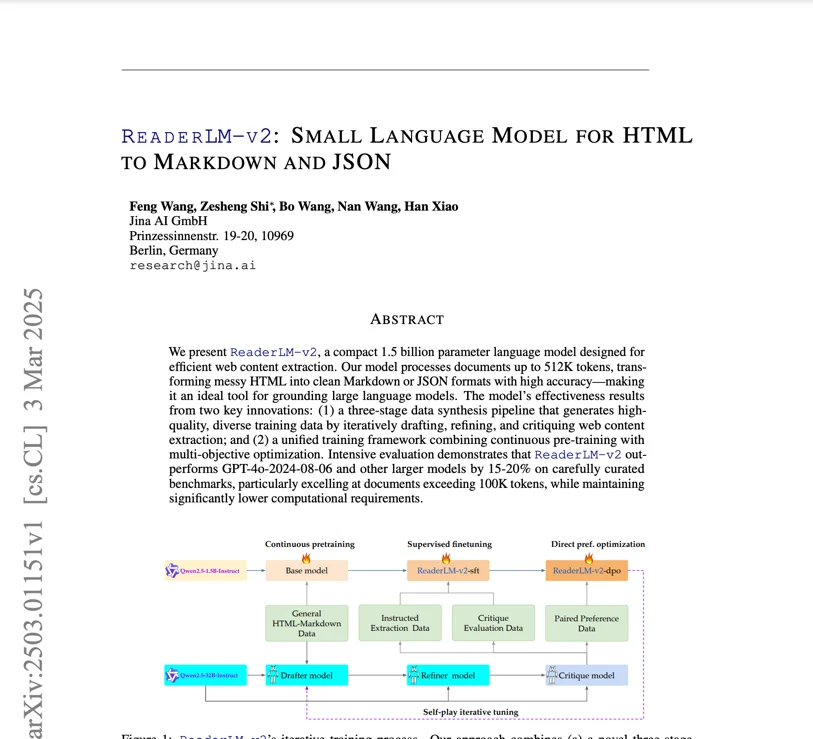
ReaderLM-v2: Small Language Model for HTML to Markdown and JSON
ACL 2025
December 17, 2024
AIR-Bench: Automated Heterogeneous Information Retrieval Benchmark
ICLR 2025
December 12, 2024
jina-clip-v2: Multilingual Multimodal Embeddings for Text and Images
ECIR 2025
September 18, 2024
jina-embeddings-v3: Multilingual Embeddings With Task LoRA
SIGIR 2025
September 07, 2024
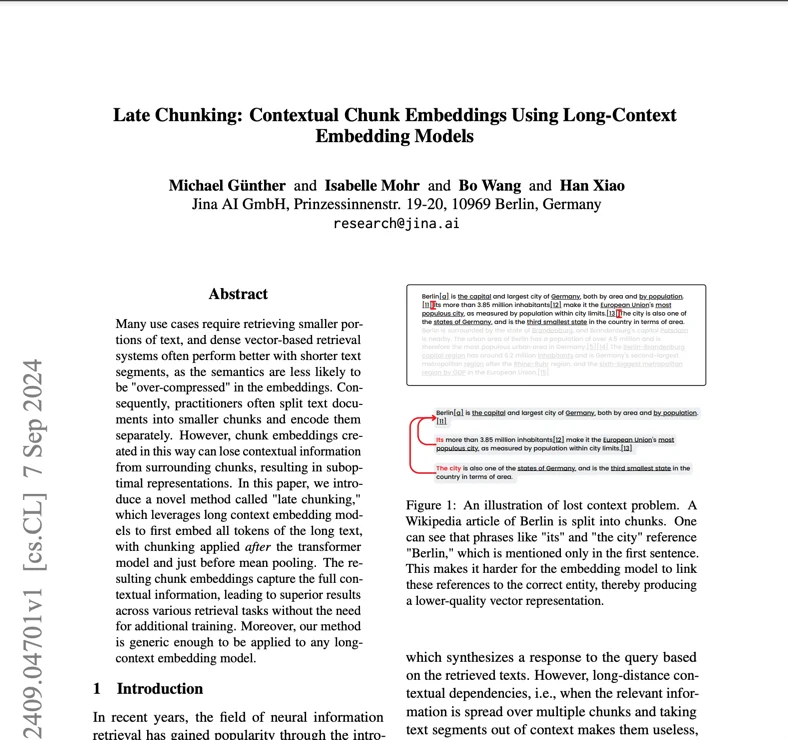
Late Chunking: Contextual Chunk Embeddings Using Long-Context Embedding Models
EMNLP 2024
August 30, 2024
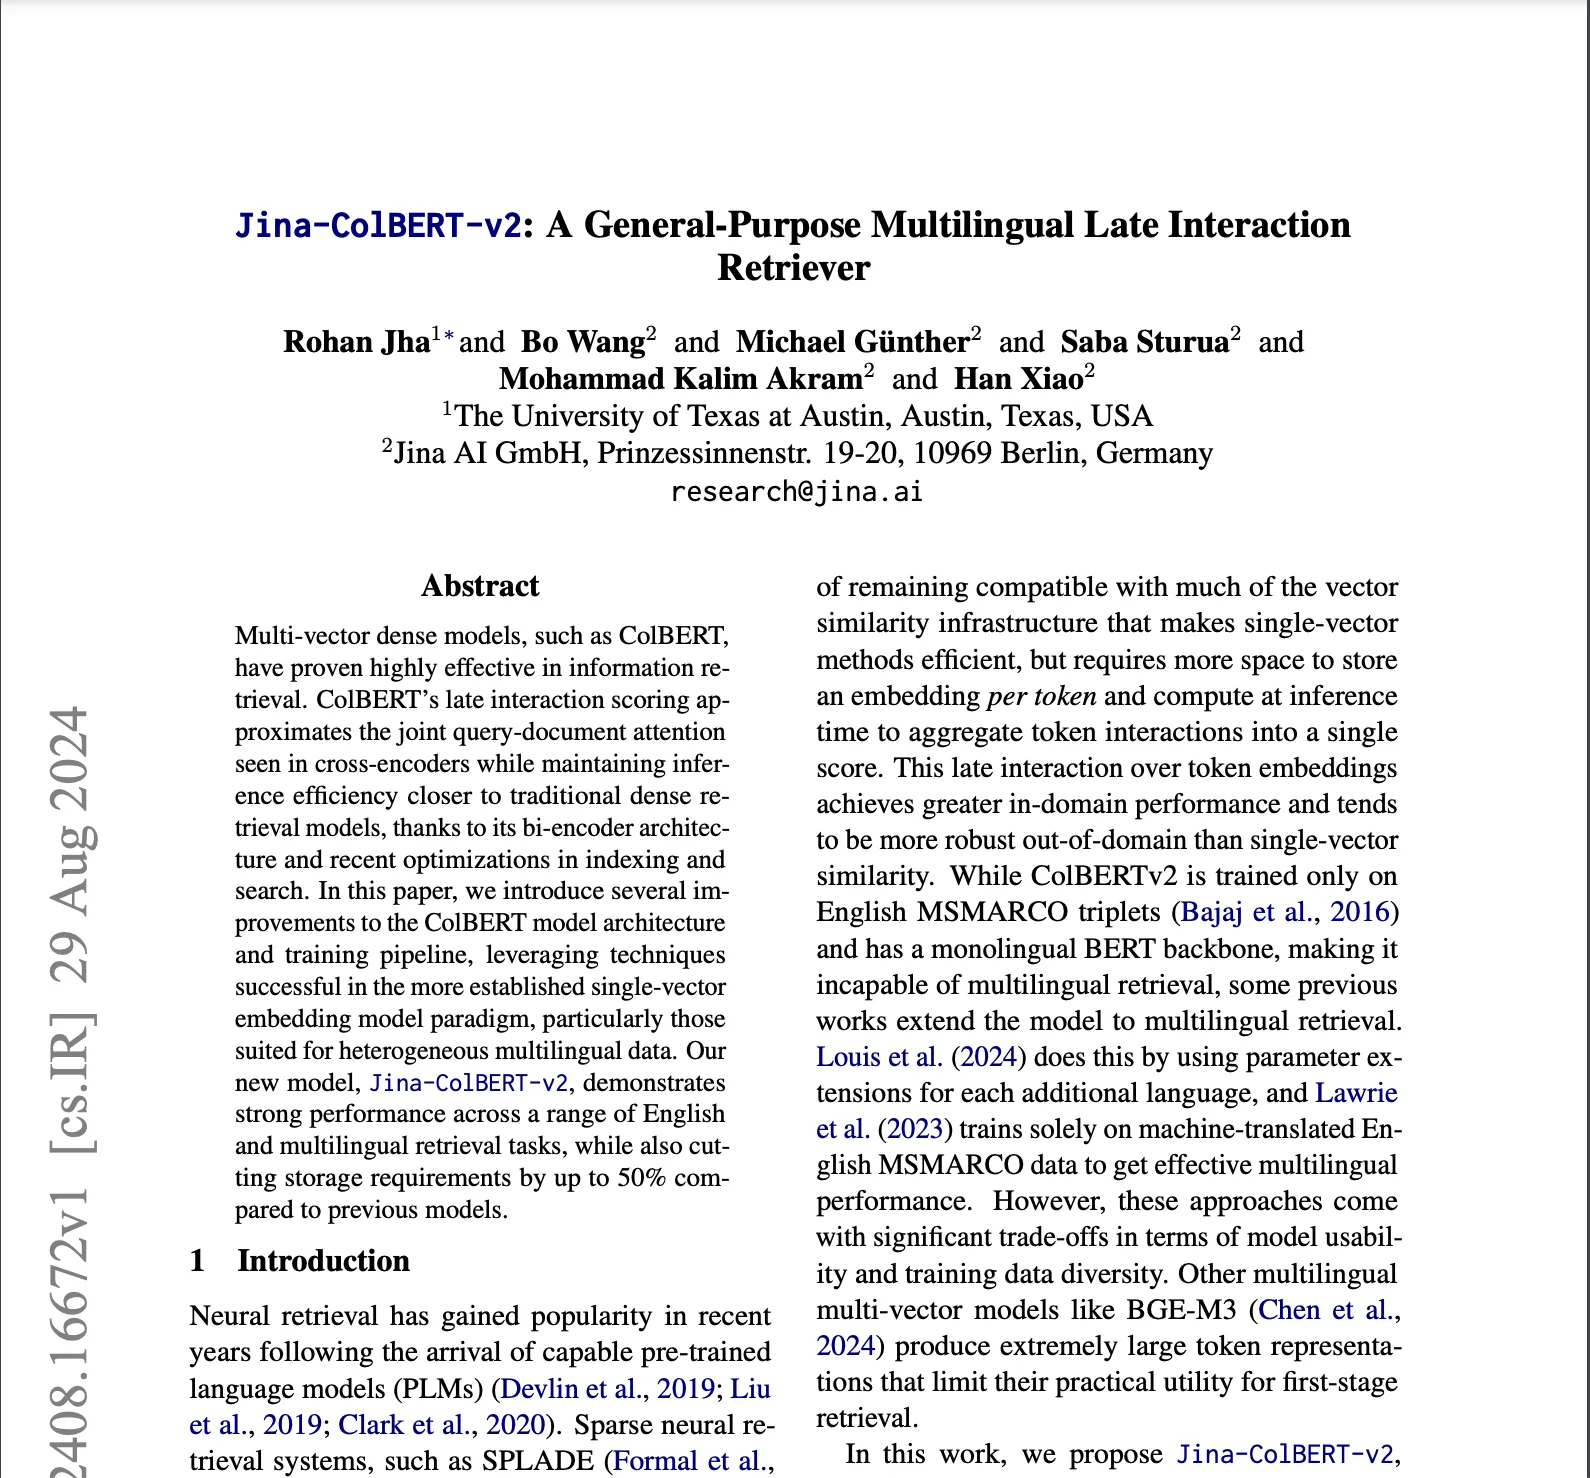
Jina-ColBERT-v2: A General-Purpose Multilingual Late Interaction Retriever
WWW 2025
June 21, 2024
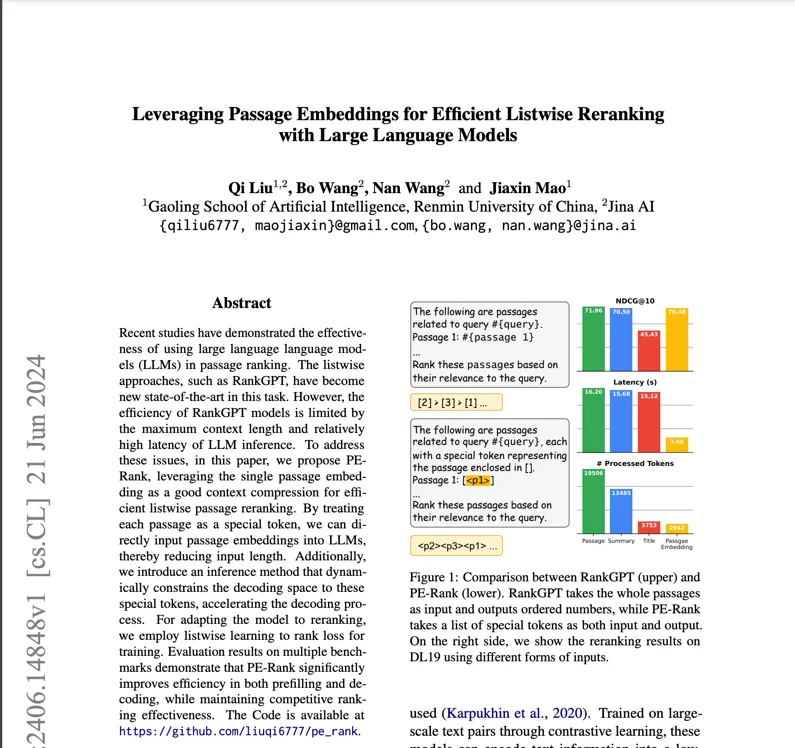
Leveraging Passage Embeddings for Efficient Listwise Reranking with Large Language Models
ICML 2024
May 30, 2024
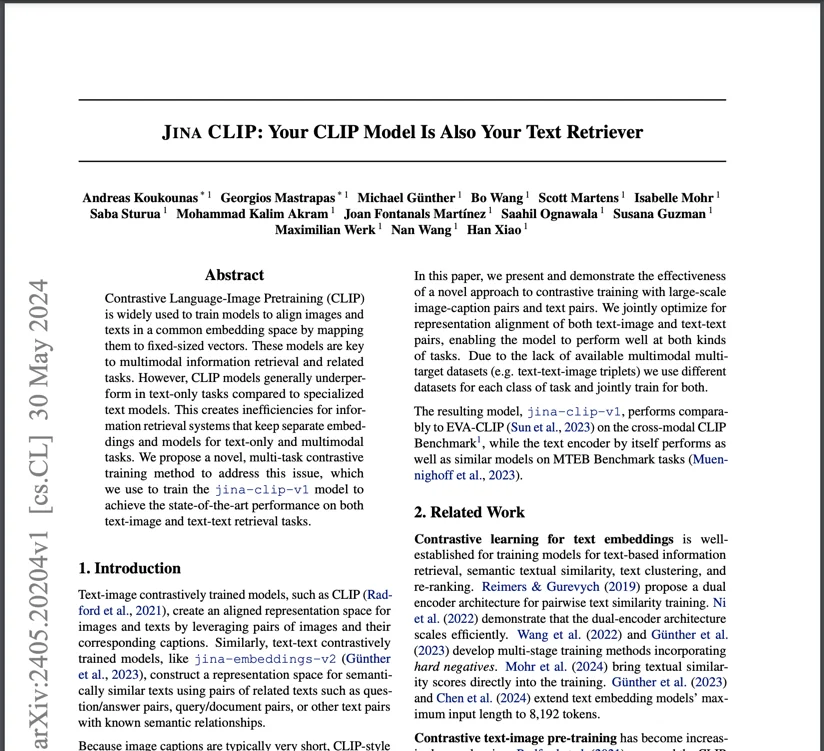
Jina CLIP: Your CLIP Model Is Also Your Text Retriever
arXiv
February 26, 2024
Multi-Task Contrastive Learning for 8192-Token Bilingual Text Embeddings
arXiv
October 30, 2023
Jina Embeddings 2: 8192-Token General-Purpose Text Embeddings for Long Documents
EMNLP 2023
July 20, 2023
Jina Embeddings: A Novel Set of High-Performance Sentence Embedding Models
21 publications in total.

September 14, 2026 • 9 minutes read
jina-ocr-v1: Faster Document Parsing on Low-Budget GPUs
jina-ocr-v1 is a vision language model with 3.4B parameters and 570M active parameters, scoring 91.1 on OmniDocBench v1.6 and 83.4 on olmOCR-Bench.
August 03, 2026 • 11 minutes read
jina-reranker-v3.5: Faster Listwise Reranking with Hybrid Attention and Self-Distillation
A 0.6B listwise reranker that beats Qwen3-Reranker-4B on BEIR, reranks up to 1.56x faster than v3, and gains 9.6 nDCG@10 on semi-structured retrieval.
May 12, 2026 • 7 minutes read
jina-embeddings-v5-omni: Embeddings for Text, Image, Audio and Video
One model, four modalities: text, image, audio, video. Best-in-class omni embeddings in 1.6B and 0.9B.
March 11, 2026 • 7 minutes read
Bootstrapping Audio Embeddings from Multimodal LLMs
Turn any multimodal LLM into a small audio embedding model that beats CLAP with 25x less data.
March 06, 2026 • 6 minutes read
Identifying Embedding Models from Raw Numerical Values
A tiny transformer that fingerprints embedding models by reading raw numerical digits. No feature engineering.
February 19, 2026 • 7 minutes read
jina-embeddings-v5-text: New SOTA Small Multilingual Embeddings
Two sub-1B multilingual embeddings with best-in-class performance, available on Elastic Inference Service, Llama.cpp and MLX.
December 04, 2025 • 7 minutes read
Jina-VLM: Small Multilingual Vision Language Model
New 2B vision language model achieves SOTA on multilingual VQA, no catastrophic forgetting on text-only tasks.
October 03, 2025 • 7 minutes read
Jina Reranker v3: 0.6B Listwise Reranker for SOTA Multilingual Retrieval
New 0.6B-parameter listwise reranker that considers the query and all candidate documents in a single context window.
September 09, 2025 • 11 minutes read
Multimodal Embeddings in Llama.cpp and GGUF
We brought multimodal embeddings to llama.cpp and GGUF, and uncovered a few surprising issues along the way.
September 04, 2025 • 6 minutes read

Jina Code Embeddings: SOTA Code Retrieval at 0.5B and 1.5B
Code generation LLMs → code embeddings: 0.5B/1.5B models achieve SOTA performance across 25 code retrieval benchmarks.